The Problem
The state of training data
AI training data is still chaotic.
Whether you're searching for existing datasets, labeling raw data, or building golden evaluation sets, AI teams juggle a tangled mess of platforms, contractor pipelines, spreadsheets, and untracked internal folders. The data wrangling never stops.
Today / The current state
Hugging Face
Kaggle
GitHub
Spreadsheets.xlsx
/raw-data/unlabeled
S3 buckets
Notebooks.ipynb
Enterprise Data
/cloud/raw
Label Studio
Annotator sheets
AI teams still struggle to:
- a.find datasets that fit specific AI use cases
- b.create or label new datasets without managing labelers themselves
- c.structure and organize datasets across projects, teams, and modalities
- d.evaluate quality, bias, and fine-tuning readiness before training
- e.document preprocessing decisions, lineage, and prompts
- f.govern training data for audits, compliance, and reproducibility
The Solution
One platform · Six capabilities
One workspace for your entire AI training data workflow.
/01
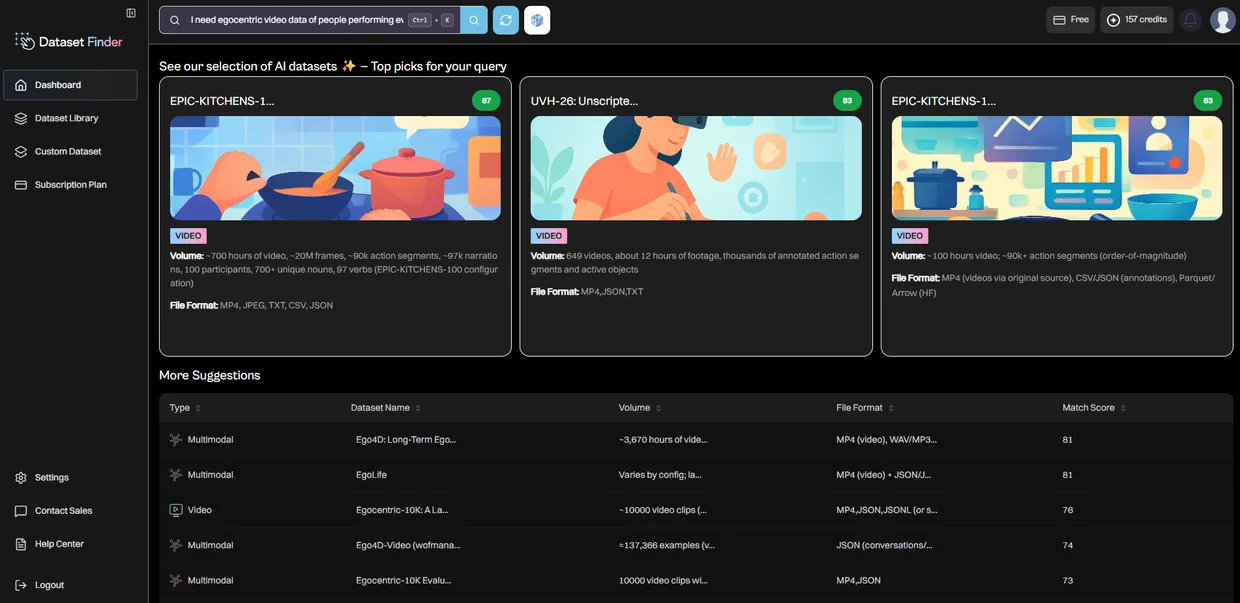
Dataset discovery
Natural-language search built for AI workloads, not keyword matching.
Tens of thousands of curated AI datasets ranked, analyzed, growing weekly
/02
Dataset intelligence
Every dataset analyzed on 30+ criteria. Quality, bias, labels, gaps, improvement ideas.
30+ analysis criteria per dataset, never start from scratch
/03
Custom data on-demand
Order datasets that don't exist yet. Pay in credits, labelers produce, you download. No crowd to manage.
Skip procurement & labeler ops we run the whole flow
/04
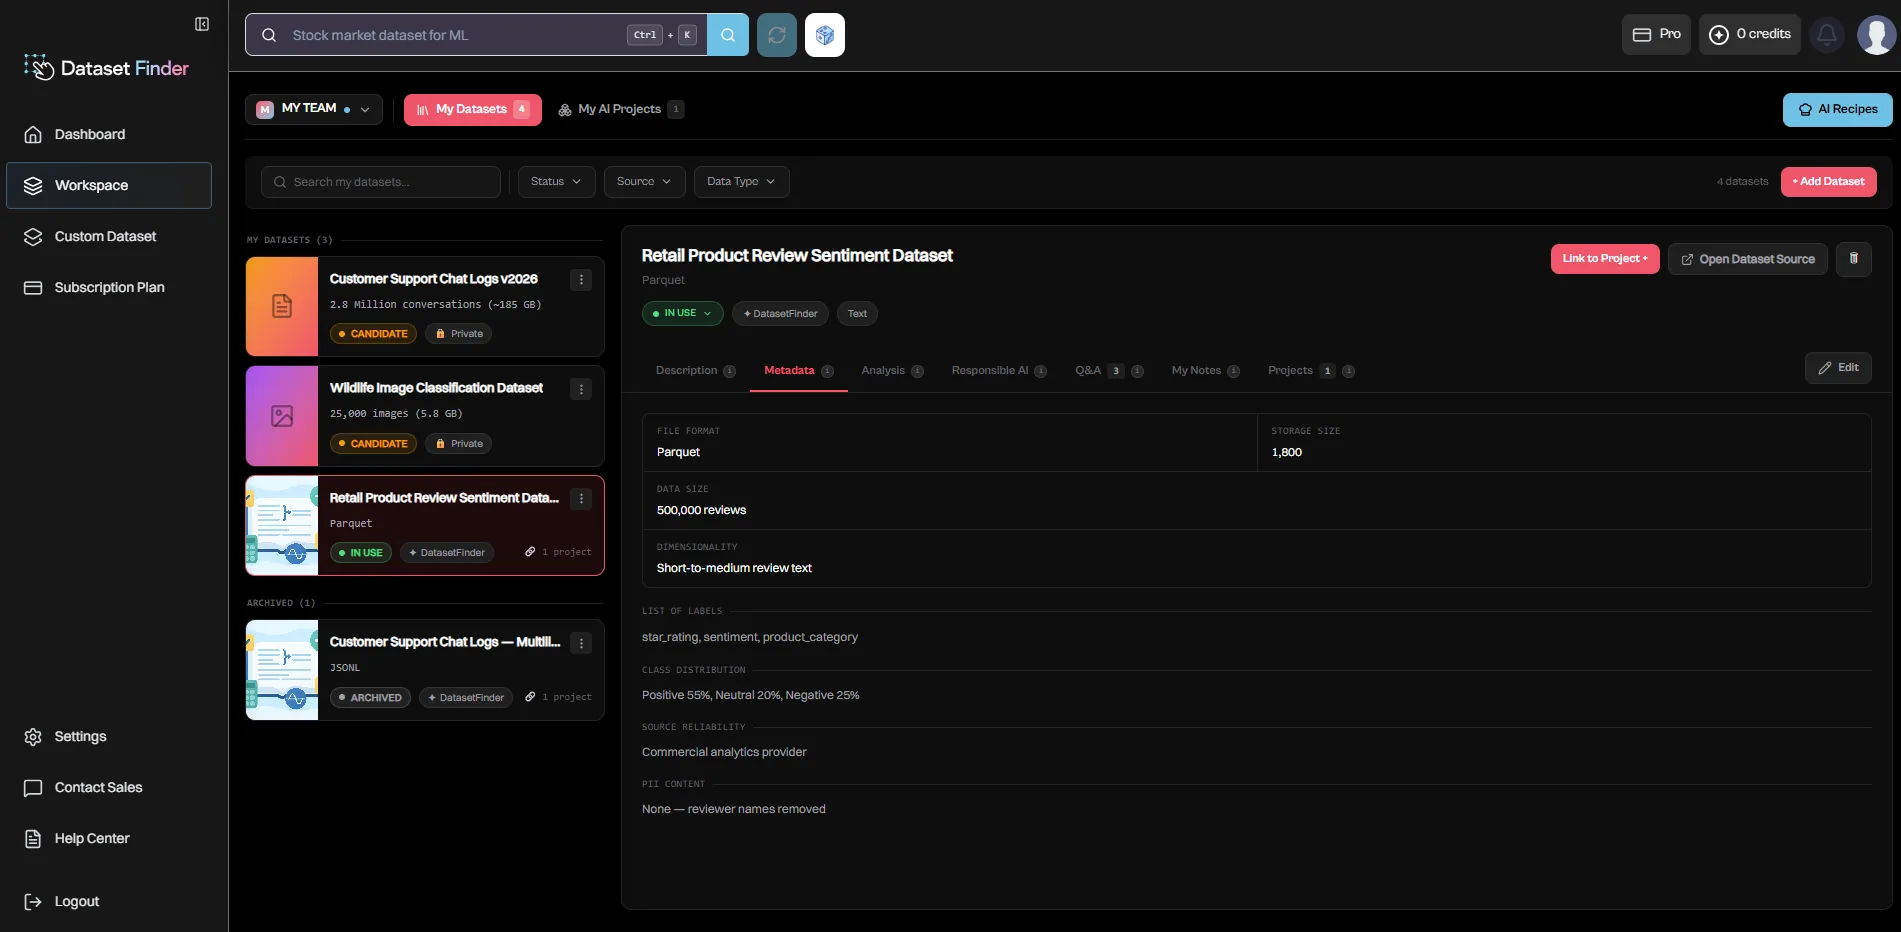
Workspace management
Projects, collections, notes, links. A real home for your datasets.
Track every dataset, project & decision across teams
/05
Projects & AI recipes
Capture winning workflows so teams can reuse what works.
Community AI recipes reviewed & validated by our team
/06
Training data inventory
Lineage, audit trail, and governance visibility for enterprise AI programs.
Built for GDPR & EU AI Act audit-ready by default
Backed by Innovatiana
Trusted experience at scale.
Dataset Finder is the new platform from Innovatiana, the data labeling team that's delivered training data to AI builders since 2021.
20M+
artifacts labeled
200+
companies served
20+
industries covered
Industries:
Autonomous Driving
Healthcare AI
Financial Services
Retail & E-commerce
Robotics
LegalTech
GenAI startups
Manufacturing
Insurance
Agriculture
Consumer Tech
Media
Use Cases
For every kind of AI team
Built for modern AI teams.
AI Startups
Accelerate fine-tuning and AI product development. Get from problem to production in weeks, not quarters.
Enterprise AI teams
Centralize training data operations, governance, and lineage across regulated AI initiatives at scale.
Researchers
Discover curated datasets faster, organize finds across papers and projects, and keep a citable record of decisions.
AI Consultants
Manage datasets across multiple AI initiatives and clients. Keep every engagement organized, billable, and audit-ready.
A day in the workspace
Meet Maya, founding CTO.
A real customer workflow, anonymised.
The challenge
Maya is building a legal copilot fine-tuned for European jurisdictions. She needs multilingual legal QA data, jurisdiction-specific case law citations, and edge-case adversarial examples. None of it exists as a single curated dataset. Buying generic legal corpora wastes weeks of cleaning, and hiring annotators herself means writing guidelines, running QA, and chasing contractors across timezones, let alone the time to invest in setting up the right labeling infrastructure and tooling before any real work begins.
How Maya uses Dataset Finder
She searches the workspace catalog for legal QA datasets to anchor the model, orders multilingual case-law citation pairs as a custom dataset with credits, and references a community recipe for adapter-based legal fine-tuning. Datasets, the custom-data brief, recipe configs, and project notes all live in one workspace.
The outcome
Maya goes from blank notebook to first eval run in 6 days. The custom dataset arrives in 3 weeks. Her team can focus on the model rather than on managing labelers.