FAQ
Workspace
From scattered links to one home

Build your AI training data workspace.

Move from scattered dataset links across Slack, Notion, and bookmarks to a single, intelligent workspace built for AI initiatives.

01

Organize datasets by project

Create dedicated projects for every AI initiative, and stop losing track of what data belongs to which model.

LLM fine-tuning AI copilots RAG systems Computer vision AI agents
02

Create dataset collections

Build reusable, themed collections that bundle datasets your team returns to across initiatives.

RLHF datasets OCR datasets Multilingual corpora Synthetic data Finance / Medical
03

Add notes & documentation

Capture preprocessing decisions, evaluation notes, and model compatibility next to the data they describe.

Preprocessing Training relevance Eval notes Governance comments
04

Link external sources

Reference Hugging Face, S3, Git, internal stores, without duplicating storage or moving terabytes around.

Hugging Face S3 buckets Git repos Cloud storage Internal datasets
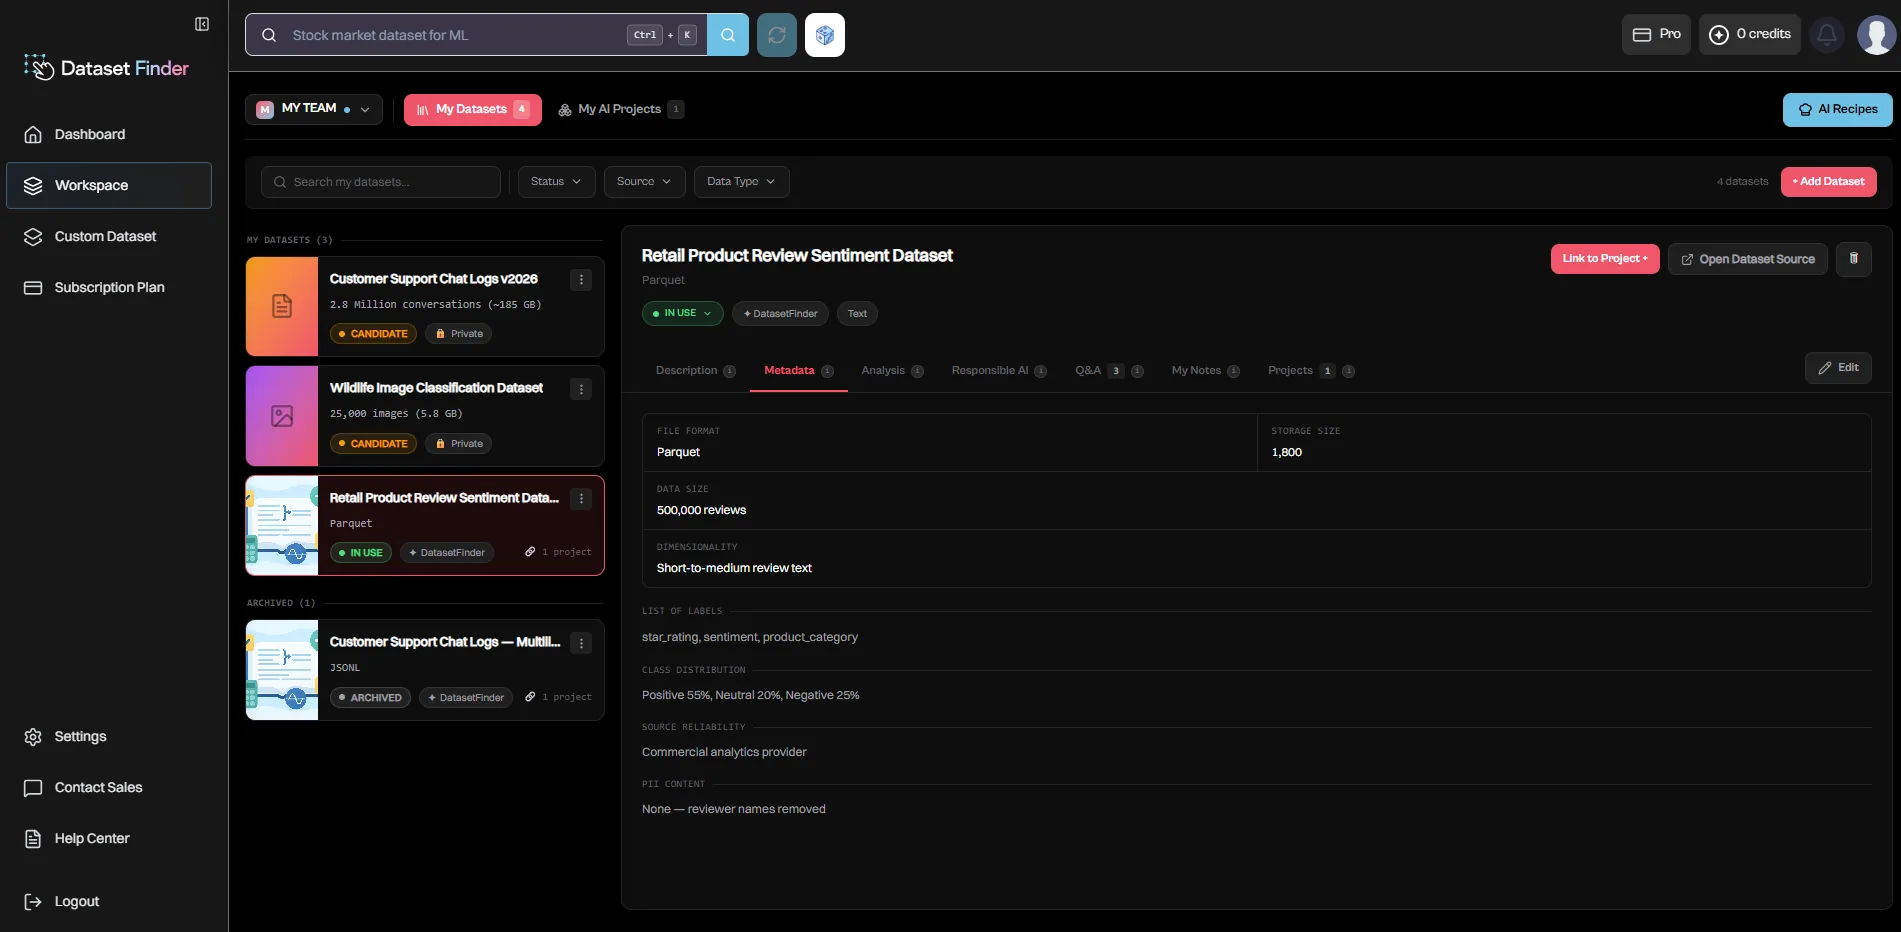
datasetfinder.co / workspace Enlarge Dataset Finder workspace showing saved datasets and dataset metadata
Your team's library. Saved datasets with status and notes, and full metadata: labels, class distribution, source reliability, PII content.
AI Projects & Recipes
Community recipes · Reviewed & validated

Start with a recipe. Not a blank notebook.

Browse a growing library of community AI training recipes, reviewed and validated by our team. From RLHF fine-tuning to multilingual OCR, each recipe ships with the datasets, model config, and pipeline that delivered production results. Clone it, adapt it, ship faster.

  • Pre-selected curated datasets
  • Model configuration ready to clone
  • Working preprocessing pipeline
  • Validated training parameters
  • Evaluation harness included
  • Architecture notes from the team that built it
RECIPE · #R-118 Multilingual Legal Assistant
PROD · v2.4
Datasets
  • Legal QA datasets
  • Multilingual instruction tuning
  • Synthetic legal conversations
  • Case law citation pairs
Model
Mistral 7B

Adapter-based fine-tuning with quantized base weights. ~6h on a single A100.

Pipeline
  • LoRA fine-tuning
  • Multilingual prompting
  • Retrieval augmentation
  • Constitutional eval
Clone recipe →

Or capture and share your own recipes as your team builds them, extending the library for the wider AI community.

Training Data Inventory
Lineage · Governance · Compliance

A centralized training data inventory.

Track how datasets flow through models, projects, and production. Maintain the visibility serious AI programs need, for audits, governance, and the EU AI Act.

huggingface.co s3://corpus-eu internal/legal synthetic-gen DS-1142 DS-2031 DS-3318 LLM v3.2 production Copilot v1 staging RAG-Legal eval SOURCES DATASETS MODELS / DEPLOYMENTS DATA LINEAGE · LIVE Active flow Production endpoint Inactive / archive 42 datasets · 9 active models · 3 regions

Inventory features

Project-to-dataset mapping
Dataset lineage
Training data tracking
Preprocessing docs
Governance metadata
Compliance notes
AI lifecycle visibility
Audit trail
Especially useful for
Enterprise AI governance Regulated industries AI audit preparation EU AI Act readiness AI risk management
Get started today

AI models improve.
Your training data workflow
should too.

Discover tens of thousands of curated AI datasets, order custom training data, and turn fragmented data pipelines into production-ready AI assets, all in one workspace.