Generative image models are trained on caption-image pairs, and this is the category where the gap between a dataset's licence and the rights in its underlying images is widest.
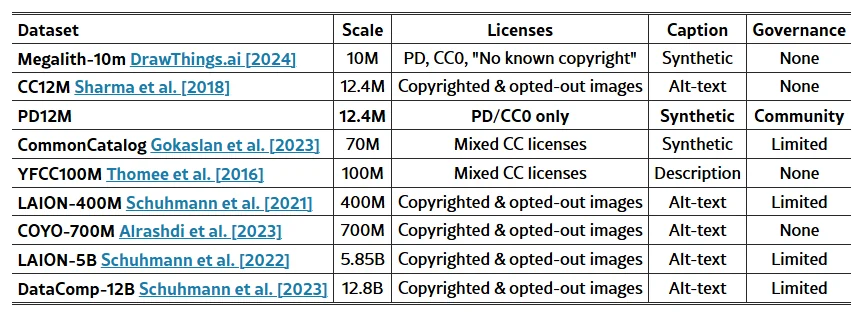
The structural issue with this category is worth understanding before you download anything. Many large image-text datasets are distributed as lists of URLs plus captions rather than as images, because distributing the images themselves would require rights the compilers do not hold. The dataset's licence then covers the list, not the pictures — and the pictures carry whatever rights their creators hold.
That distinction has become commercially significant. If you are training a generative model you intend to ship, the question is not whether the dataset is openly licensed but whether the images it points at may be used this way. The sets below whose imagery is itself public domain, CC0 or free of known copyright restrictions — PD12M, Megalith-10m and the public-domain works in The Met's collection — are a much shorter list than the sets that are merely openly packaged, and the licence column cannot tell them apart: it shows the licence on the package, not the rights in the images.
| Dataset | Modality | Size | Licence | Best for |
|---|---|---|---|---|
| Midjourney Messages | Text | 55M messages | Apache 2.0 | Text generation or conversational assistants |
| PD12M: Public Domain Image Collection | Image | 12.4M images | CC0 images + CDLA-Permissive-2.0 | Similarity search and image matching |
| Laion Aesthetics 12M UMAP | Image | 12M images | MIT | Visualising and clustering images by aesthetic |
| Megalith-10m | Image | 9.6M images | MIT | Computer vision models |
| Midjourney Prompts | Text | 9M lines | Apache 2.0 | Text-to-image generation models |
| OpenS2V-5M | Multimodal | 5M triples | CC BY 4.0 | Video generation |
| MidJourney v5 Prompt Dataset | Text | 4.2M prompts | Apache 2.0 | Prompt generation models for MidJourney |
| LAION Art EN Improved Captions | Image | 2.68M pairs | CC BY 4.0 | Text-to-image generators |
| Text-to-Image 2M | Image | 2M examples | MIT | Text-to-image models |
| Text2Video - Pika 2.2 Human Preferences | Multimodal | 756,000 responses | Apache 2.0 | Objectively evaluating text-to-video models |
| YE-POP | Image | 550,000 images | Apache 2.0 | Diffusion models to generate artistic images |
| OpenAccess - The Met Collection | Image | 470,000 works | CC0 | Computer vision for classification |
Midjourney Messages
- Size
- 55 million text messages, JSON format
- Licence
- Apache 2.0
Over 55 million raw text messages in JSON exchanged between Midjourney users, many of them tied to image generation requests. Far larger than the prompts-only sets, and includes surrounding conversation.
Training text generation or conversational assistants, analysing social dynamics in an artistic community, and studying typical queries in AI image generation.
Source: innovatiana.com
PD12M: Public Domain Image Collection
- Size
- 12.4 million public-domain images, JPEG/PNG format, 16-bit half-precision vectors (1152 dimensions) optimised for L2 indexing
- Licence
- CDLA-Permissive-2.0 for the metadata; the images are CC0 / public domain
About 12.4 million filtered public-domain images in JPEG and PNG, each with EXIF metadata, long descriptions and 1152-dimension half-precision vectors optimised for L2 indexing. Built explicitly to avoid copyright exposure.
Similarity search and image matching in large databases, training and evaluating vision or multimodal models, and building applications on EXIF metadata and embeddings.
Source: innovatiana.com
Laion Aesthetics 12M UMAP
- Size
- Approximately 12 million images with UMAP embeddings, 2.74 GB in Parquet format
- Licence
- MIT
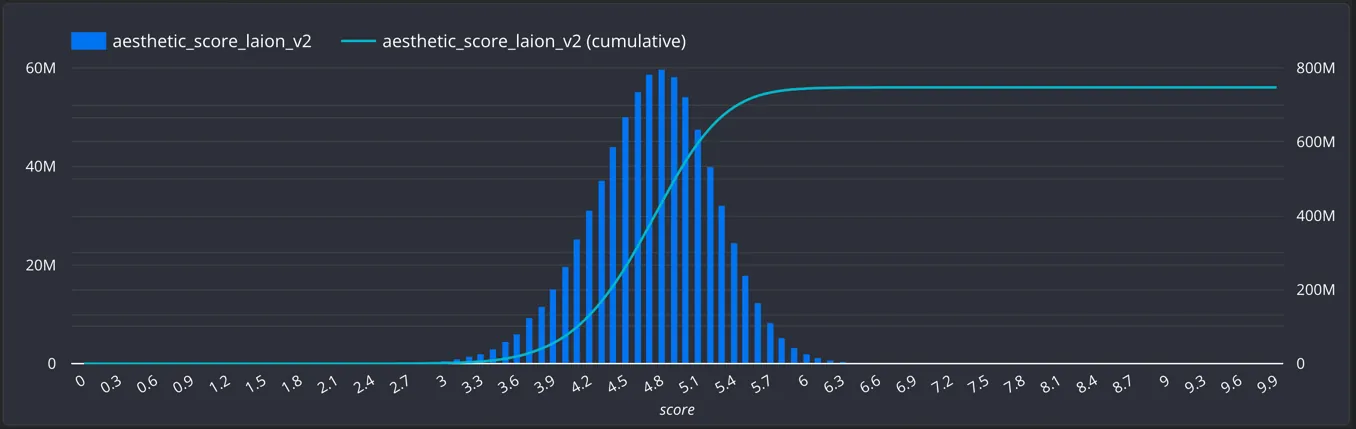
Two-dimensional UMAP projections of CLIP embeddings for roughly 12 million aesthetically filtered LAION images, 2.74 GB of Parquet, computed at three different n_neighbors settings. An exploration layer rather than an image set.
Visualising and clustering images by aesthetic quality, exploring large image sets by similarity, and building aesthetics-based recommendation systems.
Source: innovatiana.com
Megalith-10m
- Size
- Approximately 9.6 million links to images, 753 MB, Parquet format
- Licence
- MIT
About 9.6 million links to royalty-free Flickr photographs from public domain and US government sources, indexed in a 753 MB Parquet file. Links rather than pixels, so expect a substantial download step.
Training computer vision models on varied natural images, testing robustness on real diverse scenes, and establishing a base for image recognition research.
Source: innovatiana.com
Midjourney Prompts
- Size
- 9 million text lines (JSON, prompts only)
- Licence
- Apache 2.0
Nine million lines of Midjourney prompts in JSON, text only with no accompanying images. Useful as a corpus of how people actually write generative prompts, including style vocabulary and parameter conventions.
Training or refining text-to-image generation models, analysing creative trends in prompt writing, and building tools that help create optimised prompts.
Source: innovatiana.com
OpenS2V-5M
- Size
- 5 million subject-text-video triples in 720p, JSON for metadata and annotations (masks, bboxes in RLE)
- Licence
- CC-BY 4.0
Five million subject, text and video triples at 720p, with JSON metadata covering resolution, frame rate and aesthetic scores plus masks and bounding boxes in RLE format. Built for subject-consistent video generation.
Training video generation conditioned on subjects or text descriptions, developing multi-view video synthesis, and experimenting with text-subject-video models.
Source: innovatiana.com
MidJourney v5 Prompt Dataset
- Size
- 4.2 million text prompts, tabular files (.csv, .json), cleaning possible via notebook provided
- Licence
- Apache 2.0
Over 4.2 million text prompts in CSV and JSON gathered from interactions with the MidJourney Bot, covering artistic styles, detailed scenes and imaginative compositions, with a cleaning notebook supplied.
Creating or refining prompt generation models for MidJourney, DALL-E or Stable Diffusion, analysing stylistic trends in generation queries, and training visual-description NLP.
Source: innovatiana.com
LAION Art EN Improved Captions
- Size
- 2.68 million pairs of artistic images and improved captions, 442 MB, Parquet format
- Licence
- CC-BY 4.0
2.68 million artistic image-caption pairs in a 442 MB Parquet file, where the original alt-text has been replaced by improved English captions generated by a stronger model to tighten image-text alignment.
Fine-tuning text-to-image generators such as Stable Diffusion, building searchable prompt databases, and improving semantic alignment between images and descriptions.
Source: innovatiana.com
Text-to-Image 2M
- Size
- Approximately 2 million examples, 512x512 images (majority), JSON format or similar
- Licence
- MIT
Roughly two million text-image pairs, mostly at 512x512, in JSON or similar, plus a 10,000-image 1024x1024 subset for high-resolution adaptation. MIT licensed as a package; check where the underlying images came from before commercial use.
Training and refining text-to-image models, improving quality and diversity of generated images, and adapting models to high resolutions.
Source: innovatiana.com
Text2Video - Pika 2.2 Human Preferences
- Size
- 756,000 responses (JSON), low resolution GIF videos, and links to HD videos
- Licence
- Apache 2.0
About 756,000 human pairwise judgments in JSON comparing videos generated by Pika 2.2 from text prompts, with low-resolution GIF previews bundled and links out to the HD versions. A large preference corpus for video.
Objectively evaluating text-to-video models, training preference or reward models for RLHF, and analysing current limitations of video diffusion models.
Source: innovatiana.com
YE-POP
- Size
- About 550,000 image URLs in 11 chunks of 50,000, URL format
- Licence
- Apache 2.0
Eleven chunks of 50,000 image URLs each, around 550,000 artistic images in total, filtered from Laion-POP and checked both by people and for NSFW content. Distributed as URLs, so images must be fetched separately.
Training diffusion models to generate artistic images, improving automatic image captioning, and benchmarking multimodal models on artistic imagery.
Source: innovatiana.com
OpenAccess - The Met Collection
- Size
- 470,000+ works, tabular metadata (CSV/Parquet); images released separately
- Licence
- CC0 1.0
Metadata for over 470,000 Metropolitan Museum of Art works in CSV and Parquet, released under CC0. Images are not part of the dataset: the Met releases images of public-domain works separately under CC0, while images of works still in copyright are not openly licensed, so filter on the public-domain flag before using any image.
Training computer vision for classification, image search or artistic OCR once paired with the Met's separately released public-domain images, building search and cultural applications on the catalogue metadata, and enriching art history knowledge bases.
Source: innovatiana.com
How this list was put together
Shortlisted from the 28 datasets in Dataset Finder's verified set of 434 open datasets tagged “Generative AI & text-to-image”. Where the theme holds more than twelve, we prefer datasets whose licence is stated unambiguously and whose published scale is largest, so that the list is usable rather than merely long.
Sizes and licences come from each dataset's own documentation, vague wording included. Where we found a re-upload or catalogue card stating a licence that the original release contradicts, the entry gives the original terms and says so. The comparison table abbreviates licences to standard identifiers and marks vague ones as unclear.