CC0 is the most permissive position a dataset can take: the rights holder waives their rights as far as the law allows. For commercial training that removes an entire category of problem — though not quite all of it.
Of the 434 datasets we checked for this site's dataset posts, 50 carry a CC0 or public-domain dedication from their publisher. That is the subset where, on paper, you need no attribution, face no share-alike obligation and have no commercial restriction to monitor.
On paper is the operative phrase. A CC0 tag is only as good as the right of whoever applied it. We removed sets whose tag comes from a re-upload of material the uploader did not own — Flickr30k's photographs, CNN and Daily Mail articles, frames cut from YouTube videos — because the original terms for that material still apply, whatever the mirror says.
What CC0 settles is copyright in the dataset as compiled. What it does not necessarily settle is everything else: whether the content was the dedicator's to dedicate, whether personal data inside it carries privacy obligations that copyright waiver does not touch, and whether trademark or personality rights attach to anything depicted. A CC0 dataset of faces is still a dataset of faces, and biometric privacy law does not care about the copyright position.
So treat CC0 as removing the licensing question, not the diligence question. It is the best starting position available and it is a starting position.
| Dataset | Modality | Size | Licence | Best for |
|---|---|---|---|---|
| Parking Transactions Dataset | Text | 78.2M rows | CC0 | Analysing parking demand by period |
| PD12M: Public Domain Image Collection | Image | 12.4M images | CC0 images + CDLA-Permissive-2.0 | Similarity search and image matching |
| Deep Sea Corals & Sponges | Tabular | 500,000 observations | CC0 | Mapping and modelling deep-sea biodiversity |
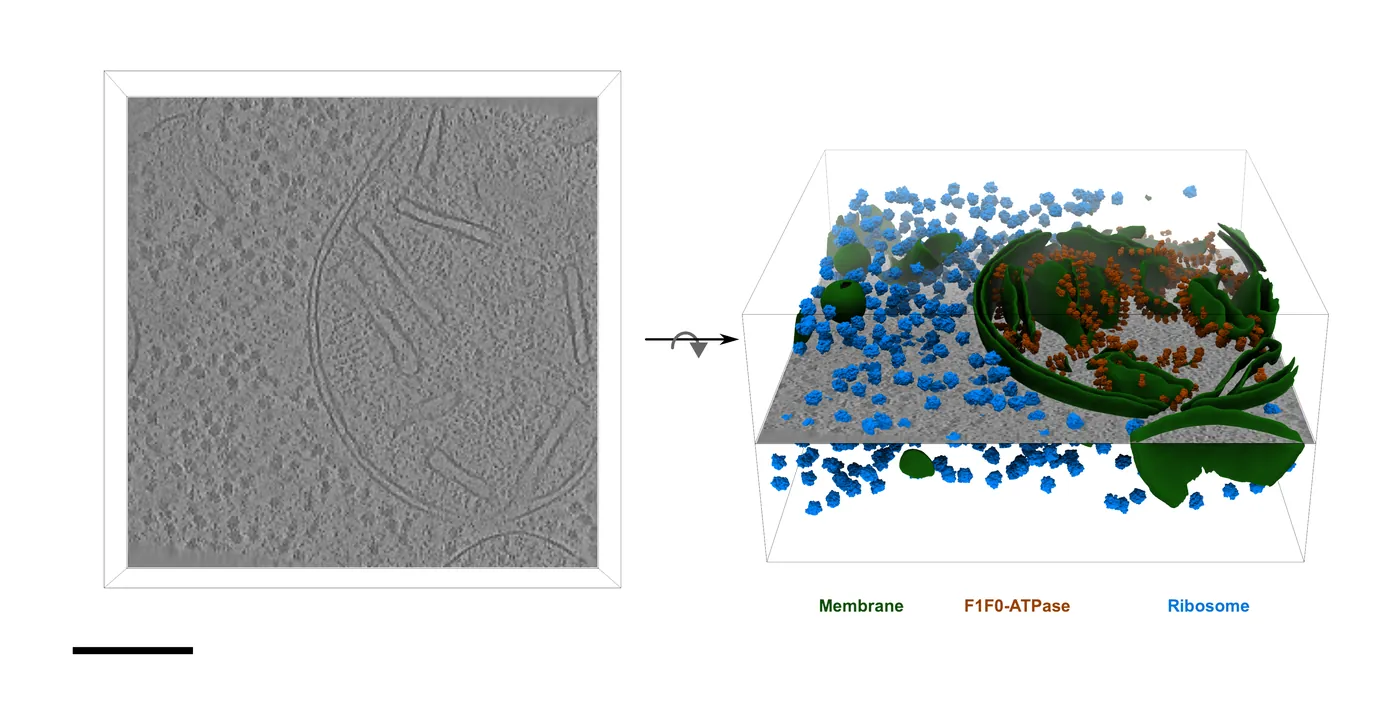
| CryoET Flagellar Motors Dataset | Medical | 167,000 files | CC0 | 3D detection models on cryo-ET data |
| Nouns | Multimodal | 49,859 images | CC0 | Text-to-image models |
| Common Voice - Audio corpus for speech recognition | Audio | 42,600 hours | CC0 | Robust ASR on diverse voice data |
| UW Madison Courses | Text | 9,000 courses | CC0 | Analysing grade and performance trends |
| New York Vehicle Collisions (2014-2023) | Text | 2.9 million rows, CSV | CC0 | Analysing accident trends across NYC geographies |
| Civil Comments - Corpus of moderated comments annotated for toxicity | Text | 2M comments | CC0 | Toxicity detection and automated moderation |
| OpenAccess - The Met Collection | Image | 470,000 works | CC0 | Computer vision for classification |
| IIT Admissions Dataset | Tabular | 200,000 records | CC0 | Admissions trends and academic preferences |
Parking Transactions Dataset
- Size
- ~78.2 million rows (CSV), data structured in 9 columns, covering 2019 to 2024
- Licence
- CC0: Public Domain
Around 78.2 million CSV rows in nine columns covering 2019 to 2024, recording transactions from parking terminals and mobile apps with duration, amount, timestamp, payment method and zone identifier. Very large for a municipal set.
Analysing parking demand by period, zone or payment method, modelling pricing policy impact, and predicting zone attendance with statistical or ML models.
Source: innovatiana.com
PD12M: Public Domain Image Collection
- Size
- 12.4 million public-domain images, JPEG/PNG format, 16-bit half-precision vectors (1152 dimensions) optimised for L2 indexing
- Licence
- CDLA-Permissive-2.0 for the metadata; the images are CC0 / public domain
About 12.4 million filtered public-domain images in JPEG and PNG, each with EXIF metadata, long descriptions and 1152-dimension half-precision vectors optimised for L2 indexing. Built explicitly to avoid copyright exposure.
Similarity search and image matching in large databases, training and evaluating vision or multimodal models, and building applications on EXIF metadata and embeddings.
Source: innovatiana.com
Deep Sea Corals & Sponges
- Size
- Over 500,000 observations, CSV files, structured tabular formats
- Licence
- CC0: Public Domain
Over 500,000 NOAA observations of deep-sea corals and sponges below 50 metres, in structured CSV, with taxonomy, location, depth, sampling method and source. Tabular records, not imagery.
Mapping and modelling deep-sea biodiversity, predicting where corals and sponges occur from depth, location and habitat, and supporting deep-sea conservation policy.
Source: innovatiana.com
CryoET Flagellar Motors Dataset
- Size
- 167,000 files (tomograms and 3D annotations) — various cryo-ET microscopy formats
- Licence
- CC0: Public Domain
167,000 files of cryo-electron tomograms with three-dimensional annotations of bacterial flagellar motors, in assorted cryo-ET microscopy formats. One of very few public datasets supporting 3D localisation of subcellular structures at this scale.
Training 3D detection models on cryo-ET data, locating subcellular structures in bacteria, and analysing flagellar motor morphology.
Source: innovatiana.com
Nouns
- Size
- 49,859 JPEG images and text captions, 328 MB, Parquet format
- Licence
- CC0-1.0
49,859 JPEG images with text captions in 328 MB of Parquet, where the descriptions are automatically generated from each item's attributes, colours and objects. Derived from the Nouns NFT art collection.
Training text-to-image models, studying the relationship between visual attributes and natural language, and evaluating automatic captioning models.
Source: innovatiana.com
Common Voice - Audio corpus for speech recognition
- Size
- About 42,600 recorded hours (29,300 validated) of MP3 clips with TSV metadata, 295 languages, as of release 27.0 (data to September 2026)
- Licence
- CC0: Public Domain
A crowdsourced multilingual collection of spoken clips in MP3 with accompanying TSV metadata, each paired with its written text: about 42,600 recorded and 29,300 validated hours across 295 languages in release 27.0, now downloaded through the Mozilla Data Collective. Mozilla's contributor model gives it unusual demographic and accent breadth, and it is released into the public domain.
Training robust ASR on diverse voice data, evaluating speech recognition by demographic and linguistic criteria, and fine-tuning on specific voices or languages.
Source: innovatiana.com
| field | line 42 | line 246 |
|---|---|---|
| Object Number | 18.11.10 | 1982.287a–c |
| Is Public Domain | True | True |
| Department | The American Wing | The American Wing |
| Object Name | Advertisement | Aviary |
| Title | Advertisement for Norwich Stone Ware Factory | Aviary |
| Object Date | 1770–1800 | ca. 1850–60 |
| Medium | Paper | Wool, twigs, moss, brass, glass |
| Dimensions | 11 x 9 in. (27.9 x 22.9 cm) | H. 29 1/2 in. (74.9 cm); Diam. 16 3/4 in. (42.5 cm) |
| Credit Line | Rogers Fund, 1918 | Friends of the American Wing Fund, 1982 |
| Country | United States | United States |
UW Madison Courses
- Size
- Over 9,000 courses, 200,000 sections, 3 million grades, SQL files and PDF snippets
- Licence
- CC0: Public Domain
Records of over 9,000 University of Wisconsin-Madison courses, 200,000 sections and 3 million grades, covering every semester since 2006, supplied as SQL files with PDF snippets, extracted from official reports.
Analysing grade and performance trends in higher education, developing NLP to extract educational information, and building course planning or academic prediction tools.
Source: innovatiana.com
New York Vehicle Collisions (2014-2023)
- Size
- 2.9 million rows, CSV
- Licence
- CC0: Public Domain
2.9 million CSV rows of police-reported traffic collisions in New York from 2014 to 2023, covering date, time, location, victims, vehicles involved and contributing factors. A decade of consistent municipal reporting.
Analysing accident trends across NYC geographies, training predictive models for collision prevention, and evaluating human, technical and environmental factors.
Source: innovatiana.com
Civil Comments - Corpus of moderated comments annotated for toxicity
- Size
- Approximately 2 million text comments in JSON format, with toxicity labels and types of abuse
- Licence
- CC0-1.0
Roughly two million English public comments in JSON, gathered from a news-site commenting plugin between 2015 and 2017, labelled for overall toxicity and for specific kinds of abuse. Public domain and large.
Training toxicity detection and automated moderation, analysing hostile online interaction dynamics, and testing multi-class and multi-label classification on long texts.
Source: innovatiana.com
OpenAccess - The Met Collection
- Size
- 470,000+ works, tabular metadata (CSV/Parquet); images released separately
- Licence
- CC0 1.0
Metadata for over 470,000 Metropolitan Museum of Art works in CSV and Parquet, released under CC0. Images are not part of the dataset: the Met releases images of public-domain works separately under CC0, while images of works still in copyright are not openly licensed, so filter on the public-domain flag before using any image.
Training computer vision for classification, image search or artistic OCR once paired with the Met's separately released public-domain images, building search and cultural applications on the catalogue metadata, and enriching art history knowledge bases.
Source: innovatiana.com
IIT Admissions Dataset
- Size
- Approximately 200,000 CSV tabular records with academic, financial, and demographic fields
- Licence
- CC0: Public Domain
Roughly 200,000 tabular CSV records on students who applied to the Indian Institutes of Technology, with academic, financial and demographic fields covering field of study, specialisation, tuition fees and discounts.
Studying admissions trends and academic preferences, analysing financial factors influencing admission, and modelling or predicting admission chances by profile.
Source: innovatiana.com
How this list was put together
Filtered to datasets whose licence field states CC0 or a public-domain dedication unambiguously; 50 of the 434 datasets qualify. Re-uploads whose CC0 tag demonstrably does not cover the content were removed after checking the original terms. Entries whose licence reads as uncertain — wording such as “Creative Commons (exact type to be specified)” — are deliberately excluded, since the point of this list is certainty.
The shortlist leads with one dataset per modality for variety, then the largest by published scale. Sizes come from each dataset's own documentation; licences were checked against the original release where a re-upload's tag looked doubtful.