Most “open” datasets permit commercial use. Fewer do so without a share-alike clause, and that distinction is the one that determines whether your obligations end at attribution.
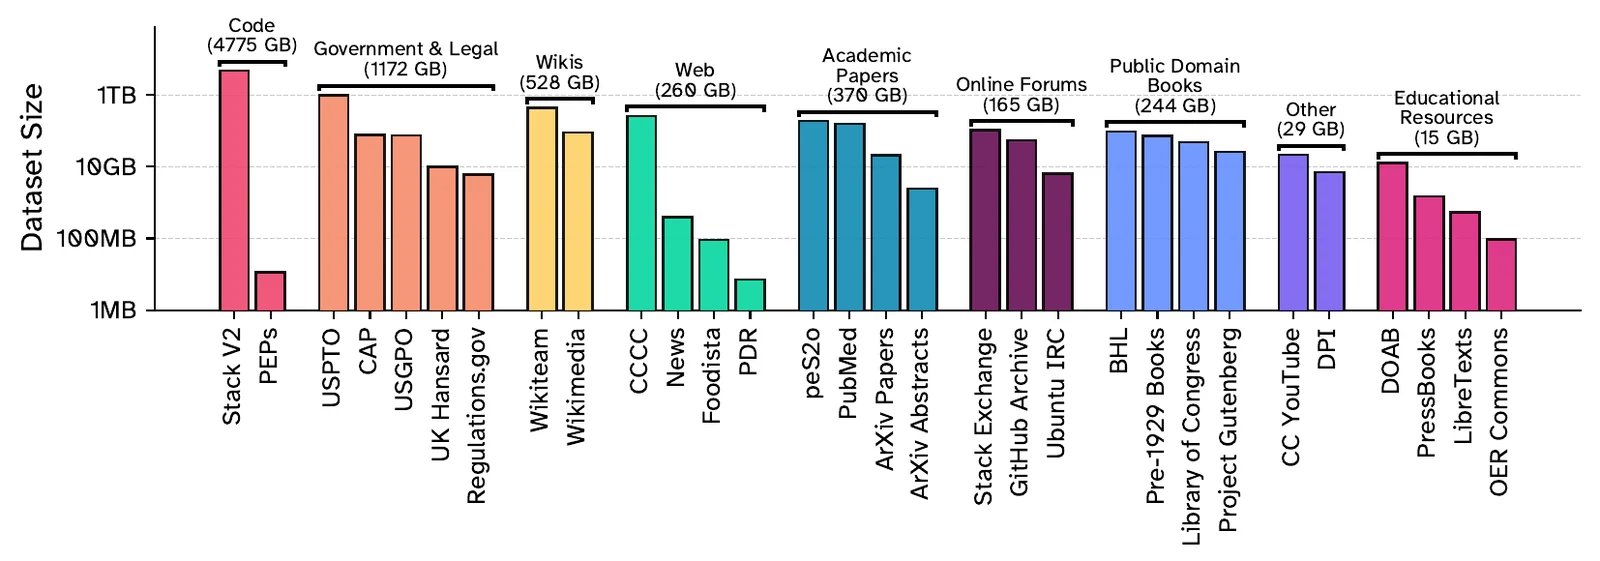
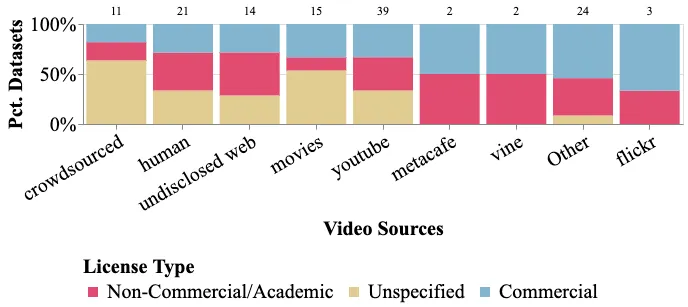
Filter the 434 datasets we checked to the clearly permissive licences — CC0, MIT, Apache 2.0, ODC-By and plain CC-BY, with non-commercial, share-alike and no-derivatives variants excluded — and 275 qualify. That number flatters the position. Many of them are collections scraped from the web, where the licence covers the URLs, captions or embeddings the publisher made, not the photographs and videos they point to.
So the 11 below were chosen by hand: sets where the publisher recorded, wrote or generated the content itself, where the content is in the public domain, or where it is public-sector open data. Each still has terms to honour, and attribution is the usual one.
The exclusions matter more than the inclusions. Non-commercial rules a dataset out of a commercial product entirely. Share-alike does not rule it out, but it carries an obligation to license derivative works you share on the same terms — and whether a model trained on share-alike data is a derivative work is genuinely unsettled rather than settled in your favour. Teams that need certainty generally keep share-alike data out of commercial pipelines for that reason alone.
CC-BY's attribution requirement is real but light: credit the source. Keep a record of which datasets you trained on and you can satisfy it. That record is worth having anyway, which is the subject of our provenance post.
| Dataset | Modality | Size | Licence | Best for |
|---|---|---|---|---|
| Common Voice - Audio corpus for speech recognition | Audio | 42,600 hours | CC0 | Robust ASR on diverse voice data |
| LibriSpeech | Audio | 1,000 hours | CC BY 4.0 | ASR models |
| Google Speech Commands | Audio | 105,000 files | CC BY 4.0 | Lightweight keyword recognition |
| Civil Comments - Corpus of moderated comments annotated for toxicity | Text | 2M comments | CC0 | Toxicity detection and automated moderation |
| Dataset Banking77 - Banking Customer Service Intentions | Text | 13,083 examples | CC BY 4.0 | NLP intent detection in banking |
| Gutenberg Dataset | Text | Several tens of thousands of books | Public domain | Text generation or completion |
| World Bank Open Data | Text | Several thousand datasets | CC BY 4.0 | Analysing global economic and social trends |
| New York Vehicle Collisions (2014-2023) | Text | 2.9 million rows, CSV | CC0 | Analysing accident trends across NYC geographies |
| PD12M: Public Domain Image Collection | Image | 12.4M images | CC0 images + CDLA-Permissive-2.0 | Similarity search and image matching |
| EuroSAT Dataset | Image | 27,000 images | MIT | Agricultural and environmental land use |
| PhysicalAI Robotics GraspGen | 3D | 57M poses | CC BY 4.0 | AI models for robotic gripping |
Common Voice - Audio corpus for speech recognition
- Size
- About 42,600 recorded hours (29,300 validated) of MP3 clips with TSV metadata, 295 languages, as of release 27.0 (data to September 2026)
- Licence
- CC0: Public Domain
A crowdsourced multilingual collection of spoken clips in MP3 with accompanying TSV metadata, each paired with its written text: about 42,600 recorded and 29,300 validated hours across 295 languages in release 27.0, now downloaded through the Mozilla Data Collective. Mozilla's contributor model gives it unusual demographic and accent breadth, and it is released into the public domain.
Training robust ASR on diverse voice data, evaluating speech recognition by demographic and linguistic criteria, and fine-tuning on specific voices or languages.
Source: innovatiana.com
LibriSpeech
- Size
- Approximately 1,000 hours of audio in FLAC format, with associated transcripts in TXT
- Licence
- CC BY 4.0
About 1,000 hours of FLAC audio from public-domain audiobook readings with word-for-word TXT transcripts. It remains the default English ASR benchmark, and unusually for this field it is cleared for commercial as well as academic use.
Training ASR models, fine-tuning or evaluating Whisper, Wav2Vec and DeepSpeech, and research on audio segmentation and audio-text alignment.
Source: innovatiana.com
Google Speech Commands
- Size
- Approximately 105,000 audio files, WAV format
- Licence
- CC BY 4.0
About 105,000 one-second WAV clips of spoken keywords recorded by many speakers, built for low-latency on-device keyword spotting. The short uniform clips make it the standard benchmark for wake-word and voice-command models.
Training lightweight keyword recognition, developing voice interfaces for IoT and home automation, and analysing short audio signals.
Source: innovatiana.com
Civil Comments - Corpus of moderated comments annotated for toxicity
- Size
- Approximately 2 million text comments in JSON format, with toxicity labels and types of abuse
- Licence
- CC0-1.0
Roughly two million English public comments in JSON, gathered from a news-site commenting plugin between 2015 and 2017, labelled for overall toxicity and for specific kinds of abuse. Public domain and large.
Training toxicity detection and automated moderation, analysing hostile online interaction dynamics, and testing multi-class and multi-label classification on long texts.
Source: innovatiana.com
Dataset Banking77 - Banking Customer Service Intentions
- Size
- 13,083 text examples with intent labels (77 classes)
- Licence
- CC-BY 4.0
13,083 real banking customer service requests, each labelled with one of 77 fine-grained intent categories. The high class count over short utterances makes it the standard hard intent-classification benchmark.
Training NLP intent detection in banking, improving customer-service chatbots or voice assistants, and analysing user needs and frustrations in detail.
Source: innovatiana.com
Gutenberg Dataset
- Size
- Several tens of thousands of books, TXT and EPUB format
- Licence
- Public domain, under Project Gutenberg terms and conditions. Verification required for commercial redistributions
Several tens of thousands of public domain literary works in TXT and EPUB from Project Gutenberg, spanning novels, essays, theatre and poetry. Commercial redistribution requires checking Gutenberg's own terms.
Training text generation or completion, linguistic and stylistic analysis across authors, automatic summarisation or literary classification, and studying language change over time.
Source: innovatiana.com
World Bank Open Data
- Size
- Several thousand datasets in CSV and XLSX formats
- Licence
- CC BY 4.0 by default for World Bank datasets; some datasets carry their own terms
Several thousand individual datasets in CSV and XLSX covering economic, social and environmental indicators for hundreds of countries across long time series. The standard open reference for cross-country development data.
Analysing global economic and social trends, academic research in economics and social sciences, predictive modelling for public policy, and validating data science models.
Source: innovatiana.com
New York Vehicle Collisions (2014-2023)
- Size
- 2.9 million rows, CSV
- Licence
- CC0: Public Domain
2.9 million CSV rows of police-reported traffic collisions in New York from 2014 to 2023, covering date, time, location, victims, vehicles involved and contributing factors. A decade of consistent municipal reporting.
Analysing accident trends across NYC geographies, training predictive models for collision prevention, and evaluating human, technical and environmental factors.
Source: innovatiana.com
PD12M: Public Domain Image Collection
- Size
- 12.4 million public-domain images, JPEG/PNG format, 16-bit half-precision vectors (1152 dimensions) optimised for L2 indexing
- Licence
- CDLA-Permissive-2.0 for the metadata; the images are CC0 / public domain
About 12.4 million filtered public-domain images in JPEG and PNG, each with EXIF metadata, long descriptions and 1152-dimension half-precision vectors optimised for L2 indexing. Built explicitly to avoid copyright exposure.
Similarity search and image matching in large databases, training and evaluating vision or multimodal models, and building applications on EXIF metadata and embeddings.
Source: innovatiana.com
EuroSAT Dataset
- Size
- 27,000 labelled 64x64 pixel images in 10 classes, RGB JPG and 13-band multispectral TIFF
- Licence
- MIT (the authors' release); Sentinel data under the Copernicus terms
27,000 labelled Sentinel-2 satellite tiles at 10 metre resolution and 64x64 pixels, supplied both as RGB JPG and as multispectral TIFF, sorted into ten land-use and land-cover classes. The multispectral option is what sets it apart from ordinary image sets.
Classifying agricultural and environmental land use, building geospatial change monitoring tools, and benchmarking vision methods on multispectral imagery.
Source: innovatiana.com
PhysicalAI Robotics GraspGen
- Size
- 57 million grasp poses in WebDataset format (.tar), JSON for splits
- Licence
- CC-BY 4.0
57 million simulated grasp poses in WebDataset .tar archives with JSON split files, generated across 8,515 Objaverse XL 3D objects and three gripper types. Published by NVIDIA. It holds grasp poses and object references, not images.
Training AI models for robotic gripping in simulation, testing Sim2Real approaches for 3D object manipulation, and creating benchmarks for different gripper types.
Source: innovatiana.com
How this list was put together
Filtered to licences matching CC0, MIT, Apache 2.0, ODC-By or CC-BY, with non-commercial, share-alike and no-derivatives variants excluded and vague licence wording excluded; 275 of 434 datasets pass. From those, the list keeps only sets whose content the publisher created or owned, public-domain material and public-sector open data, leaving out web-scraped collections whose licence covers the packaging rather than the media.
This is a mechanical filter on the licence as published, not a legal opinion about your specific use. Verify the current licence on the dataset's own page before you rely on it — licences do change, and a dataset's terms at the time we checked are not a guarantee of its terms today.