Vision-language models need paired image and text, and the pairing quality matters far more than the pair count. These are the open sets worth starting from, with their licences stated as published.
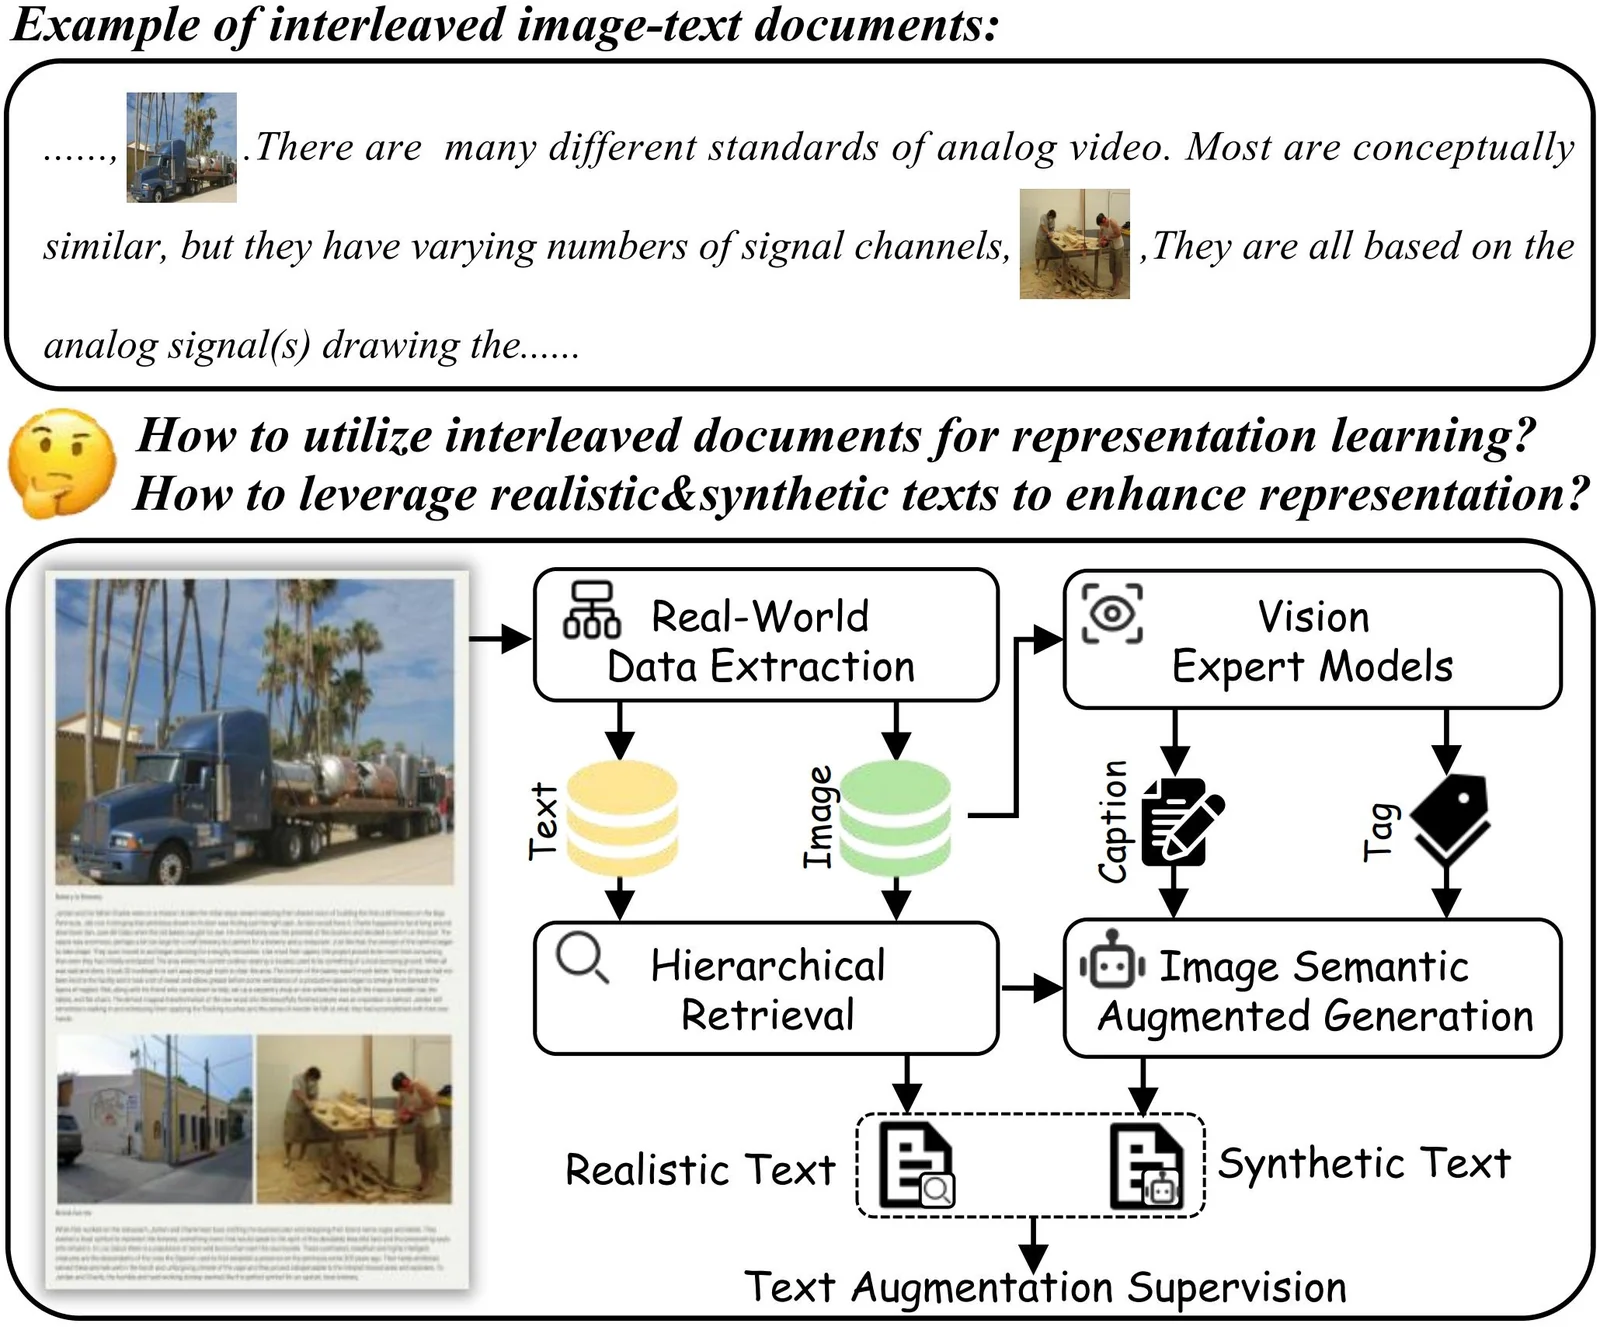
A multimodal dataset can mean several quite different things, and the distinction decides whether a set is useful to you. Caption datasets pair one image with one short description, and suit contrastive pretraining. Visual question answering sets pair an image with a question and an answer, and suit instruction tuning. Interleaved document sets preserve the original ordering of images and text on a page, which is what you need for models that reason over documents rather than over photographs.
The practical warning for this category is that published counts are often the number of pairs before filtering, and several of the largest sets contradict their own names — one dataset named for 200 million images (BLIP3-OCR-200M, not on this list) shows about 96 million rows, and MAmmoTH-VL Instruct 12M, below, shows 37 million rows. Where that happens below, the entry says so rather than repeating the name's figure.
| Dataset | Modality | Size | Licence | Best for |
|---|---|---|---|---|
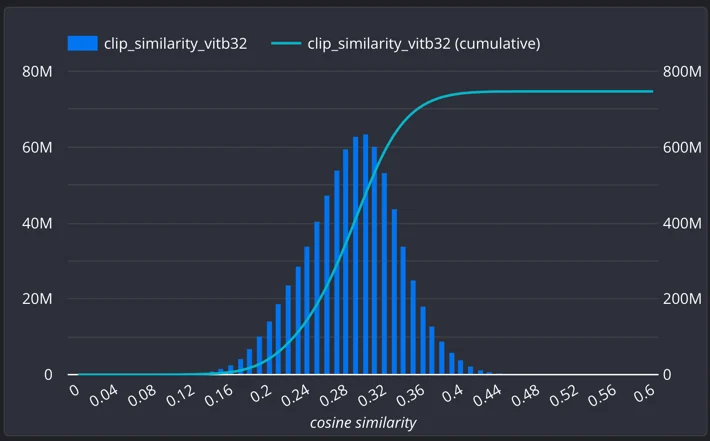
| Coyo 700M | Multimodal | 747M images | CC BY 4.0 | Multimodal vision-language models at scale |
| Blip3 Kale | Multimodal | 218M pairs | Apache 2.0 | Large vision-language models |
| RealSyn100m | Multimodal | 100M examples | MIT | Large multimodal models |
| MAmmoTH-VL Instruct 12M | Multimodal | 37M rows | Apache 2.0 | Multimodal models |
| BLIP3o Long Caption Dataset | Multimodal | 27M images | Apache 2.0 | Automatic visual description generation |
| Marqo GS 10M | Multimodal | 9.8M items | Apache 2.0 | Multimodal product search engines |
| WIT Base | Multimodal | 6.5M examples | CC BY-SA 3.0 | Combine images and text |
| Moondream2 COYO 5M Captions | Image | 5M pairs | CC BY-SA 4.0 | Text-to-image generation |
| MMPR v1.2 | Multimodal | 3M samples | MIT | Visual comprehension combined with reasoning |
| VisualWebInstruct | Multimodal | 900,000 pairs | Apache 2.0 | Multimodal models |
| Cambrian Alignment Dataset | Multimodal | 291,750 rows | Apache 2.0 | Aligning vision-language models for contextual understanding |
| UVT Explanatory Based Vision Tasks | Image | 284,000 triples | MIT | Vision models to follow complex instructions |
Coyo 700M
- Size
- Approximately 747 million image+text pairs, 135 GB in Parquet files
- Licence
- CC-BY 4.0
Roughly 747 million image-and-text pairs harvested from HTML documents, 135 GB of Parquet. One of the largest openly licensed image-text corpora, used as a LAION alternative for training vision-language foundation models.
Training multimodal vision-language models at scale, improving visual and textual comprehension in multimodal LLMs, and complementing other foundation-model corpora.
Source: innovatiana.com
Blip3 Kale
- Size
- Approximately 218 million image-text pairs, Parquet format, 6.87 GB per split
- Licence
- Apache 2.0
About 218 million image-caption pairs in Parquet at 6.87 GB per split, where captions are dense and enriched with web-sourced knowledge rather than being short alt-text. Salesforce-published and Apache licensed.
Pre-training large vision-language models, improving factual and detailed image description generation, and research into knowledge-enriched image understanding.
Source: innovatiana.com
RealSyn100m
- Size
- Up to 100 million examples, including images and associated texts, several formats used depending on the splits
- Licence
- MIT
Up to 100 million examples pairing real images with synthetic or extracted texts, in formats that vary by split. Semantic balancing is applied so rarer concepts are better represented than in raw web scrapes.
Pre-training or refining large multimodal models such as CLIP variants, improving detailed image representation, and generalising better on rare concepts.
Source: innovatiana.com
MAmmoTH-VL Instruct 12M
- Size
- Approximately 37 million rows (12 million instruction-response pairs per the paper), 5 GB minimum, Parquet format
- Licence
- Apache 2.0
Roughly 37 million rows of multimodal instruction data in Parquet, at least 5 GB, pairing images with instructions and step-by-step rationales across diverse, reasoning-heavy tasks. The paper counts 12 million instruction-response pairs, so check how rows map to examples before quoting a size.
Training multimodal models to solve complex visual problems, producing detailed explanatory answers for scientific questions, and testing visual instructional reasoning.
Source: innovatiana.com
BLIP3o Long Caption Dataset
- Size
- Approximately 27 million images with captions (~120 tokens), WebDataset tar shards (Hugging Face also serves an auto-converted Parquet copy)
- Licence
- Apache 2.0
Roughly 27 million images in WebDataset tar shards, each paired with a lengthy AI-generated description of about 120 tokens. Caption length is the distinguishing feature versus short alt-text corpora.
Training automatic visual description generation, pre-training multimodal systems on complex images, and cross-modal search between long text and images.
Source: innovatiana.com
Marqo GS 10M
- Size
- Approximately 9.8 million multimodal items (text + images), 212 GB, Parquet format
- Licence
- Apache 2.0
Roughly 9.8 million multimodal items across 212 GB of Parquet, pairing text descriptions with images of Google Shopping products. One of the largest open e-commerce multimodal retrieval corpora.
Improving multimodal product search engines, training ranking and information retrieval for e-commerce, and experimenting with multimodal contrastive learning.
Source: innovatiana.com
WIT Base
- Size
- About 6.5 million examples (6,477,255; the dataset viewer previews only the first 5.15 GB, about 108,000 rows), multilingual images and captions, Parquet format
- Licence
- CC BY-SA (upstream WIT is CC BY-SA 3.0)
About 6.5 million Wikipedia image-and-caption examples in Parquet (the viewer previews only the first 5.15 GB, about 108,000 rows), with captions in many languages. Wikimedia provenance makes it one of the cleanest multilingual image-text sources available.
Training models that combine images and text across several languages, improving multimodal translation and image description, and testing robustness on real-world data.
Source: innovatiana.com
Moondream2 COYO 5M Captions
- Size
- 5 million image-text pairs, 1.5 GB, image and text formats (captions)
- Licence
- CC-BY-SA 4.0
Five million image-text pairs totalling 1.5 GB, extracted from COYO-700M and recaptioned with long descriptions by the Moondream2 vision-language model, prompted with each image's alt text, from images pre-filtered for aesthetic score, watermark score and CLIP similarity. Hosted on ModelScope.
Training text-to-image generation, developing automatic image annotation and understanding, and improving long caption quality in multimodal applications.
Source: innovatiana.com
MMPR v1.2
- Size
- About 3 million preference samples (image, question, chosen and rejected response), 54.7 GB
- Licence
- MIT
A multimodal reasoning preference dataset of about 3 million samples (54.7 GB), each an image and question with a chosen and a rejected response, used for Mixed Preference Optimization of InternVL models and reported against benchmarks such as MathVista, MathVision and POPE.
Improving visual comprehension combined with reasoning, training models for complex VQA, and testing robustness against visual hallucinations.
Source: innovatiana.com
VisualWebInstruct
- Size
- About 900,000 QA pairs (40% visual), Parquet, 1.55 GB
- Licence
- Apache 2.0
About 900,000 instruction-style question-answer pairs in Parquet, 1.55 GB, with roughly 40 percent carrying an associated image, spanning mathematics, physics, finance, chemistry and other fields. Harvested from the web rather than hand-written.
Training multimodal models to reason over combined text and images, improving responses across scientific fields, and testing robustness on visual and textual QA.
Source: innovatiana.com
Cambrian Alignment Dataset
- Size
- 291,750 rows, over 50 GB, files archived in tar
- Licence
- Apache 2.0
291,750 rows across more than 50 GB of tar archives, holding question-answer pairs for aligning multimodal text-and-image models, drawn together from LLaVA, Mini-Gemini, ALLaVA and ShareGPT4V.
Training and aligning vision-language models for contextual understanding, evaluating LLM response quality on multimodal tasks, and creating robust multimodal benchmarks.
Source: innovatiana.com
UVT Explanatory Based Vision Tasks
- Size
- Approximately 284,000 image-instruction-output triples, 5.5 GB (Parquet format)
- Licence
- MIT
Roughly 284,000 triples of image, natural-language explanatory instruction and expected output, 5.5 GB in Parquet, unifying several computer vision tasks under one instruction-following format.
Training vision models to follow complex instructions, improving zero-shot generalisation across vision tasks, and seeking unified approaches to vision tasks.
Source: innovatiana.com
How this list was put together
Shortlisted from the 45 datasets in Dataset Finder's verified set of 434 open datasets tagged “Multimodal / vision-language”. Where the theme holds more than twelve, we prefer datasets whose licence is stated unambiguously and whose published scale is largest, so that the list is usable rather than merely long.
Sizes and licences come from each dataset's own documentation, vague wording included. Where we found a re-upload or catalogue card stating a licence that the original release contradicts, the entry gives the original terms and says so. The comparison table abbreviates licences to standard identifiers and marks vague ones as unclear.