Time series work has one failure mode that dominates all others, and it produces results that look very good indeed.
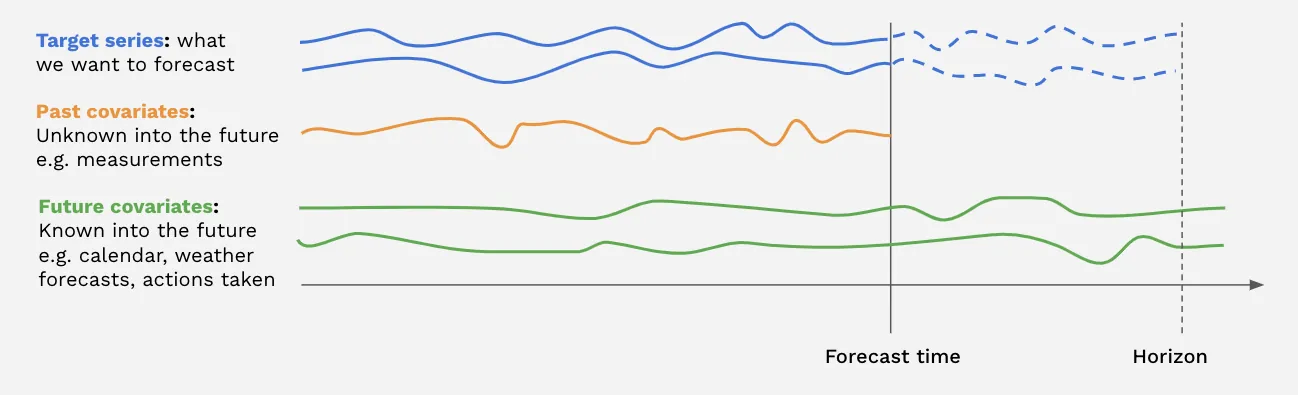
The mistake is splitting randomly. Shuffling time series rows into train and test sets lets the model see the future of the very series it is predicting, and the resulting accuracy is spectacular and meaningless. Splits must be chronological: train on earlier data, test on later, with a gap if your features have any lookback.
The related subtlety is feature leakage through aggregates. Normalising by a mean computed over the whole series, or including a rolling feature whose window extends past the prediction point, leaks future information without any obvious split violation. If your forecasting results seem too good, this is almost always why — check the feature construction before the model.
| Dataset | Modality | Size | Licence | Best for |
|---|---|---|---|---|
| FreshRetailNet-50k - Food Retail Demand Prediction | Text | 4.85M records | CC BY 4.0 | Demand forecasting in food retail |
| Beam-Level Traffic Timeseries | Text | 2,880 beams | MIT | Forecasting network load |
| Parking Transactions Dataset | Text | 78.2M rows | CC0 | Analysing parking demand by period |
| Fannie Mae Loan Performance Dataset | Text | Several million records | Research only | Default scoring and forecasting models |
| Quandl Stock Market Data | Text | Several tens of millions of records | Unclear — see below | Predictive models |
| IMF Data (International Monetary Fund) | Text | Several thousand economic indicators | IMF terms | Comparative studies between countries or regions |
| World Bank Open Data | Text | Several thousand datasets | CC BY 4.0 | Analysing global economic and social trends |
| Kaggle Financial Datasets | Text | Multiple financial data… | Unclear — see below | Price or trend forecasting |
| MIMIC-III | Medical | 40,000 records | Research only | Mapping intensive-care pathways |
FreshRetailNet-50k - Food Retail Demand Prediction
- Size
- 4.85 million daily store-product records with hourly sales profiles (CSV/Parquet)
- Licence
- CC BY 4.0
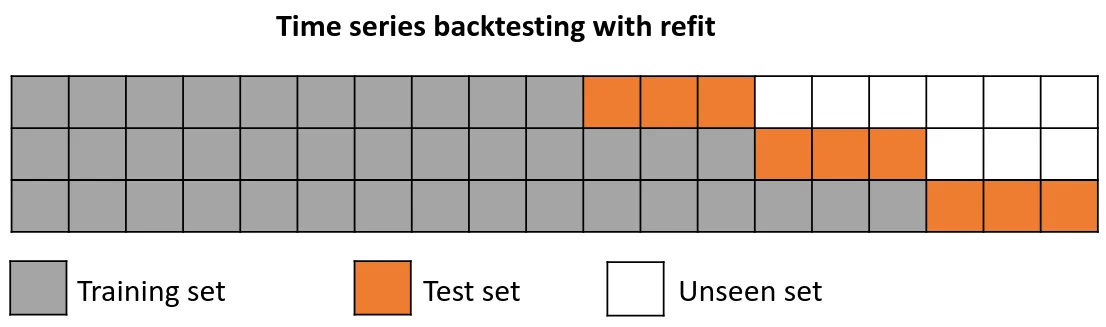
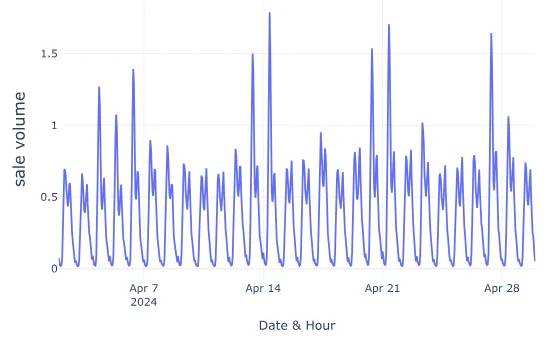
4.85 million daily store-product records (4.5 million train, 350,000 eval) in CSV and Parquet, each with an hour-by-hour sales profile, covering 50,000 series over 90 days of perishable food sales across 898 stores in 18 cities, with stockout flags, promotions, weather and holiday context. A proper demand-forecasting benchmark.
Improving demand forecasting in food retail, testing stockout and latent demand detection, and training large-scale contextual time series models.
Source: innovatiana.com
Beam-Level Traffic Timeseries
- Size
- 2,880 beams, CSV files, 1,176 hours of data per beam
- Licence
- MIT
Time series of 5G network traffic for 2,880 beams across 30 base stations in CSV, with 1,176 hours of data per beam, covering downlink volume, transmission time, PRB usage and users per beam. Rare open telecom data.
Forecasting network load to optimise 5G resource management, training time series models for mobile traffic, and researching user behaviour at cell level.
Source: innovatiana.com
Parking Transactions Dataset
- Size
- ~78.2 million rows (CSV), data structured in 9 columns, covering 2019 to 2024
- Licence
- CC0: Public Domain
Around 78.2 million CSV rows in nine columns covering 2019 to 2024, recording transactions from parking terminals and mobile apps with duration, amount, timestamp, payment method and zone identifier. Very large for a municipal set.
Analysing parking demand by period, zone or payment method, modelling pricing policy impact, and predicting zone attendance with statistical or ML models.
Source: innovatiana.com
Fannie Mae Loan Performance Dataset
- Size
- Several million records, CSV format
- Licence
- Free access for research and analysis, with registration required on the official platform
Several million CSV records of US residential mortgages guaranteed by Fannie Mae, tracking loan performance over time for analysing real-estate credit trends and modelling default risk. Registration on the official platform is required.
Training default scoring and forecasting models, analysing mortgage market stability, evaluating lending policies, and simulating macroeconomic housing scenarios.
Source: innovatiana.com
Quandl Stock Market Data
- Size
- Several tens of millions of records, CSV and JSON formats (including several free datasets)
- Licence
- Licence to be verified feed by feed: free or commercial depending on the supplier on Nasdaq Data Link (formerly Quandl)
A platform, now Nasdaq Data Link (Nasdaq bought Quandl in 2018), aggregating stock, index, interest rate and bond data from several vetted providers, several tens of millions of records in CSV and JSON. Licensing varies by supplier, so each feed must be checked individually.
Training predictive models on stock prices and trends, developing algorithmic trading strategies, quantitative finance research, and simulating portfolio risk.
Source: innovatiana.com
IMF Data (International Monetary Fund)
- Size
- Several thousand economic indicators, CSV and Excel format
- Licence
- IMF Copyright and Usage terms: reuse with attribution; commercial reuse and LLM training need the IMF's permission
Several thousand macroeconomic and financial indicators in CSV and Excel, maintained by the International Monetary Fund and covering countries worldwide. Free to reuse with attribution under the IMF's own terms, which require permission for commercial reuse and for training large language models.
Comparative studies between countries or regions, monitoring global macroeconomic trends, economic research, and training predictive models for growth or debt.
Source: innovatiana.com
World Bank Open Data
- Size
- Several thousand datasets in CSV and XLSX formats
- Licence
- CC BY 4.0 by default for World Bank datasets; some datasets carry their own terms
Several thousand individual datasets in CSV and XLSX covering economic, social and environmental indicators for hundreds of countries across long time series. The standard open reference for cross-country development data.
Analysing global economic and social trends, academic research in economics and social sciences, predictive modelling for public policy, and validating data science models.
Source: innovatiana.com
Kaggle Financial Datasets
- Size
- Multiple financial data sets, CSV formats
- Licence
- Not specified for the collection: each Kaggle dataset carries its own licence, so check it before use
A collection pointer rather than one dataset: multiple CSV financial datasets on Kaggle covering historical market prices, cryptocurrency, macroeconomic indicators, transaction and order book data, and synthetic backtesting data. Licences vary per dataset.
Training price or trend forecasting, developing algorithmic trading systems, studying financial behaviour and volumes, and evaluating investment strategies on historical data.
Source: innovatiana.com
MIMIC-III
- Size
- Over 40,000 patient records, CSV formats
- Licence
- Credentialed access under the PhysioNet Credentialed Health Data License 1.5.0: CITI human-research training and a signed data use agreement are required
Detailed intensive-care clinical records for more than 40,000 patients, developed at MIT and distributed as CSV. The data covers 2001 to 2012 and includes treatments, diagnoses and outcomes, behind an authentication step and a confidentiality agreement.
Mapping intensive-care pathways, forecasting mortality or length of stay, researching personalised medicine, and creating clinical decision support tools.
Source: innovatiana.com
How this list was put together
Found by searching Dataset Finder for datasets whose documentation describes the task, then checked by hand. A keyword match is not a fit — the first pass picked up a coral survey for the depth-estimation list because it was recorded below fifty metres — so every entry was read against what this page covers, and the ones that matched a word without matching the task were removed.
Sizes and licences come from each dataset's own documentation, vague wording included. Where we found a re-upload or catalogue card stating a licence that the original release contradicts — a CC0 tag on Flickr photographs, MIT on data whose terms require a signed agreement — the entry gives the original terms and says so. The comparison table abbreviates licences; hover a cell for the full wording.