Translation needs aligned sentence pairs, and the alignment quality of large mined corpora varies far more than their size figures suggest.
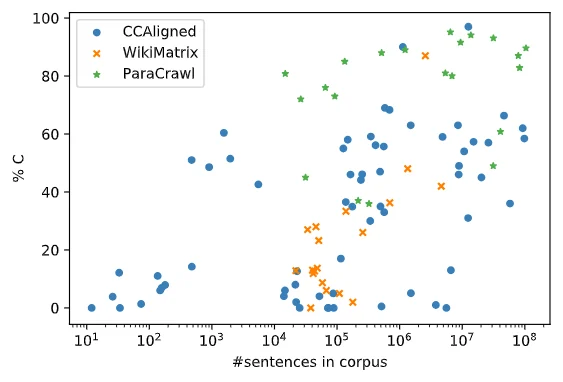
Parallel data comes from three places, in descending order of quality and ascending order of volume. Professionally translated documents — parliamentary proceedings, official publications — are accurate and narrow in register. Aligned web content is broader and noisier. Automatically mined pairs from comparable corpora give the largest volumes and contain genuinely mismatched pairs, sometimes at double-digit rates.
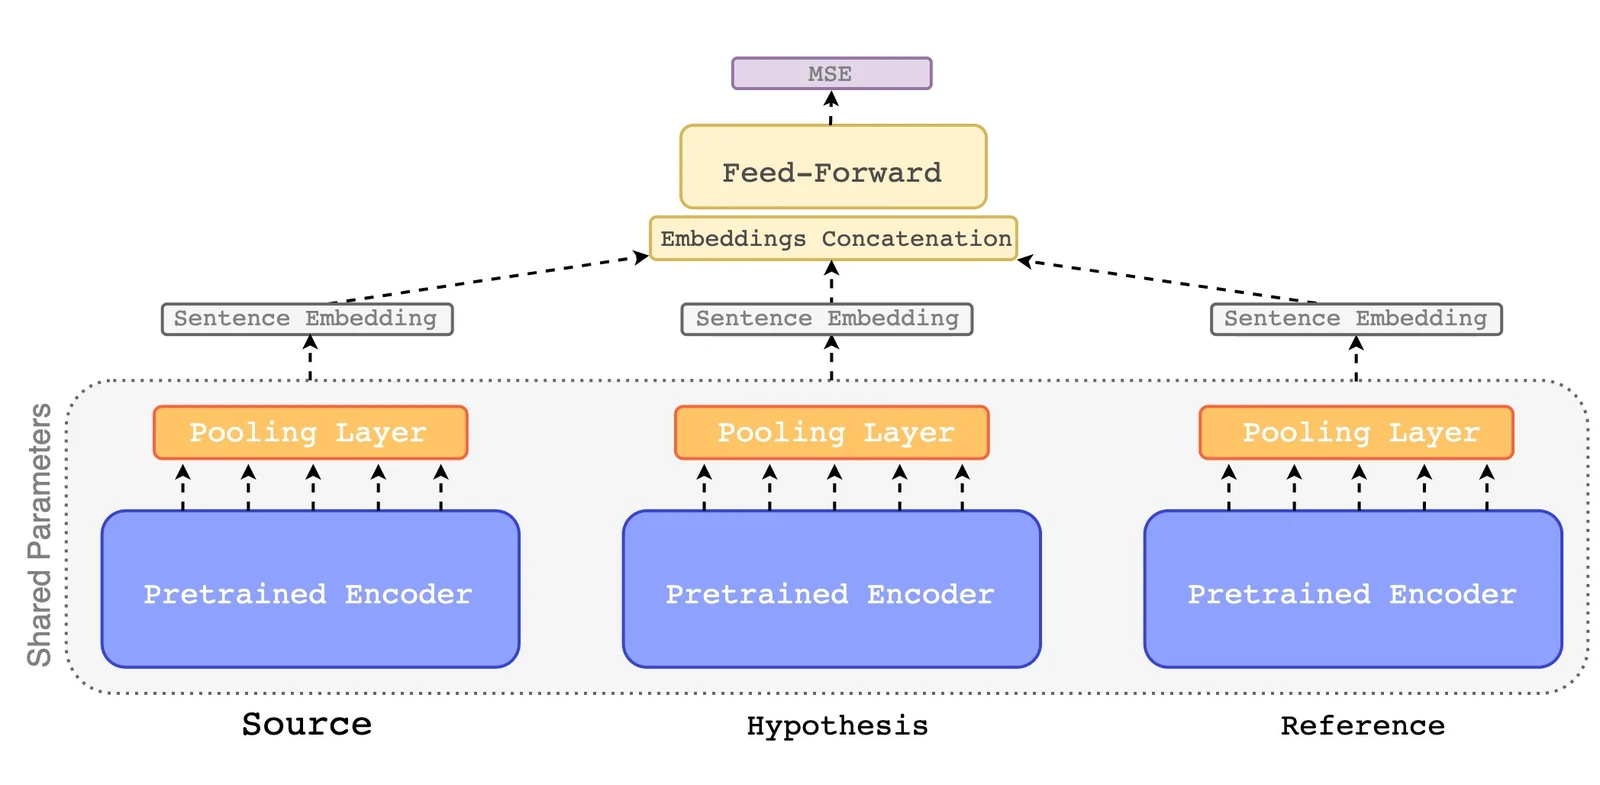
For low-resource languages, expect the honest supply to be thin. Headline language counts in large multilingual corpora usually refer to languages present at all, not languages present usefully, and pair counts drop by orders of magnitude outside the top handful. Scope that before committing to a language pair — it is often the difference between a fine-tuning project and a data-collection project.
Four is a short list on purpose. Translation data is usually discussed by volume, and the large mined collections are a different kind of object from the sets below — aligned automatically, of uneven quality, and published under terms that vary corpus by corpus inside the same collection. What is here is one large web-collected language pair, one evaluation set across more than two hundred languages, a human-judgement set for scoring translation quality, and the source audio of a speech translation training set. If you need a language pair not covered, the evaluation set is the place to start: build your benchmark first, then assess any mined parallel data against it.
| Dataset | Modality | Size | Licence | Best for |
|---|---|---|---|---|
| English—French Parallel Translation Dataset | Text | 22,500,000 sentences | ODbL | High-performance machine translation |
| FLORES+: Multilingual Translation Benchmark | Text | 2,000 sentences | CC BY-SA 4.0 | Translation models |
| WMT SQM Human Evaluation | Text | 109,600 examples | Apache 2.0 | Machine translation quality |
| StreamUni | Audio | 9,631 clips | Apache 2.0 | Live streaming speech translation |
English—French Parallel Translation Dataset
- Size
- ~22,500,000 aligned sentences, text format (TSV/CSV) two columns (English/French)
- Licence
- Open Database License (ODbL) or equivalent
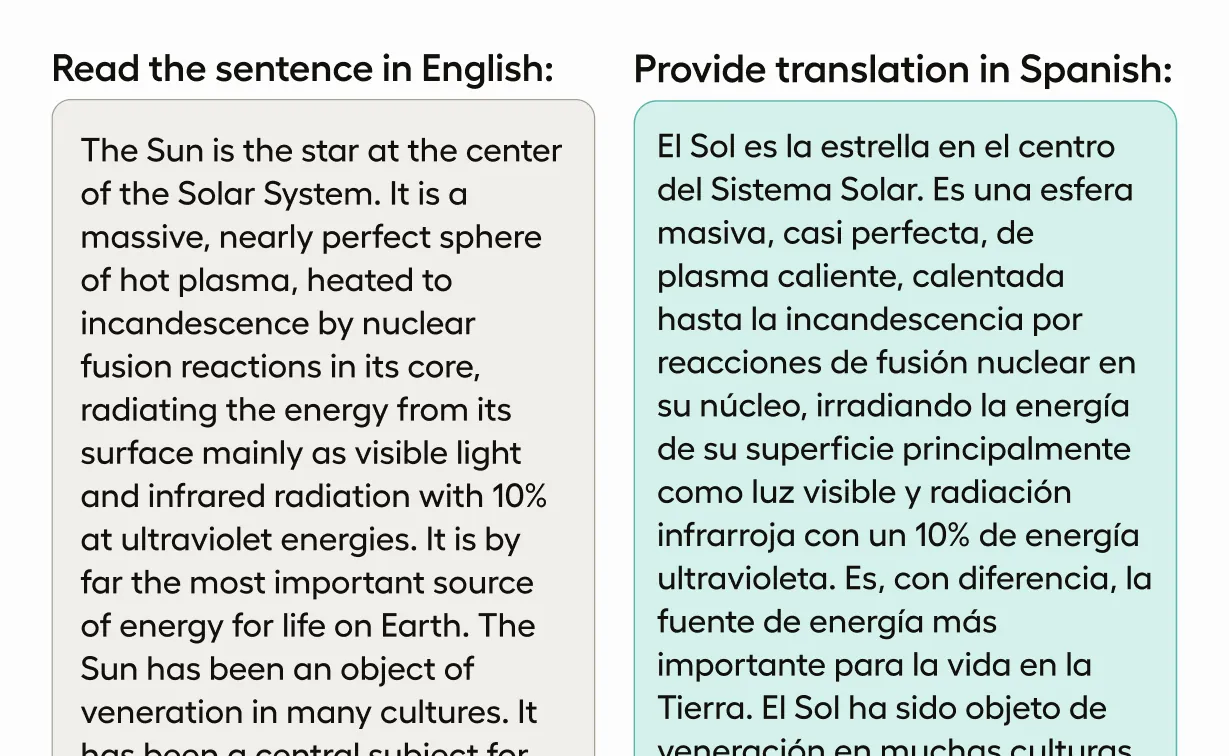
About 22.5 million aligned English-French sentence pairs in two-column TSV or CSV, gathered by web collection and used as the basis for the 2015 Workshop on Statistical Machine Translation. Very large for a single language pair.
Training high-performance machine translation, fine-tuning multilingual LLMs for translation or bilingual generation, and studying corpus alignment methods.
Source: innovatiana.com
FLORES+: Multilingual Translation Benchmark
- Size
- Approximately 2,000 sentences per language × 230 language varieties, structured text format
- Licence
- CC-BY-SA 4.0
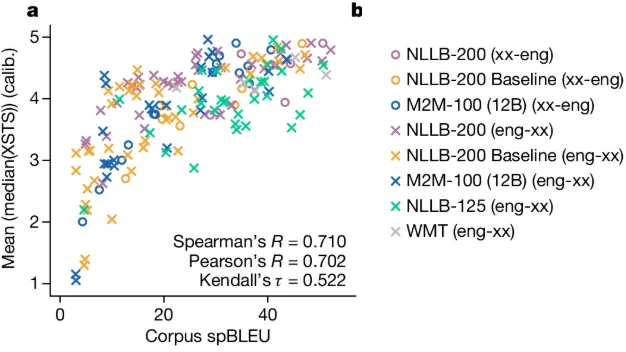
Roughly 2,000 parallel sentences per language across 230 language varieties, drawn from Wikinews, Wikivoyage and Wikijunior. One of the widest-coverage open translation benchmarks, and multi-way parallel: every language shares the same source sentences.
Evaluating translation models on low- and high-resource languages, testing multilingual systems in a controlled setting, and exploring LLM or NMT language coverage.
Source: innovatiana.com
- source
- Government Retires 15 More Senior Tax Officials On Graft Charges
| system | target | score (0–6) |
|---|---|---|
| Human-A.0 | Regierung schickt 15 weitere hochrangige Steuerbeamte wegen Bestechung in den Ruhestand | 5 |
| eTranslation.737 | Regierung scheidet aus 15 weiteren hohen Steuerbeamten wegen Graft-Gebühren aus | 1 |
| Huoshan_Translate.832 | Regierung geht 15 weitere hochrangige Steuerbeamte wegen Transplantationsgebühren in den Ruhestand | 0 |
WMT SQM Human Evaluation
- Size
- About 109,600 human evaluation examples (109,605 rows)
- Licence
- Apache 2.0
About 109,600 human DA+SQM annotations scoring machine translation quality from the WMT 2022 task, each with source text, translation, reference, score and metadata such as language pair, domain and year.
Evaluating machine translation quality, analysing inter-annotator variability and stabilising scores, and comparing MT models across domains and languages.
Source: innovatiana.com
- source
- Foreign Office advice has ramifications for travel insurance.
| system | target | category | severity |
|---|---|---|---|
| hyp.Facebook-AI | Die Empfehlung des Auswärtigen Amtes hat Auswirkungen auf die Reiseversicherung. | No-error | No-error |
| hyp.UEdin | Die Beratung des Auswärtigen Amtes hat Auswirkungen auf die Reiseversicherung. | Accuracy/Mistranslation | Major |
| hyp.eTranslation | Die Beratung durch das Auswärtige Amt hat Auswirkungen auf die Reiseversicherung. | Accuracy/Mistranslation | Minor |
StreamUni
- Size
- 9,631 MP3 audio clips (~693 MB), audio only: no transcripts or translations
- Licence
- Apache 2.0
9,631 MP3 audio clips, about 693 MB, with no transcripts or translations in the release, used to train the StreamUni-phi4 model for streaming speech translation. Built specifically for live rather than offline translation.
Training live streaming speech translation, testing real-time multilingual transcription and translation, and building voice assistants or automatic subtitling.
Source: innovatiana.com
How this list was put together
Found by searching Dataset Finder for datasets whose documentation describes the task, then checked by hand. A keyword match is not a fit — the first pass picked up a coral survey for the depth-estimation list because it was recorded below fifty metres — so every entry was read against what this page covers, and the ones that matched a word without matching the task were removed.
Sizes and licences come from each dataset's own documentation, vague wording included. Where we found a re-upload or catalogue card stating a licence that the original release contradicts — a CC0 tag on Flickr photographs, MIT on data whose terms require a signed agreement — the entry gives the original terms and says so. The comparison table abbreviates licences; hover a cell for the full wording.