Multilingual data is abundant for a dozen languages and thin for the rest, and that unevenness is the defining feature of the category rather than an incidental gap.
Two shapes serve different purposes. Parallel corpora pair the same content across languages and train translation directly. Multilingual monolingual corpora — large text collections in many languages, not aligned — are what you use for continued pretraining to give a model competence in a language it barely saw.
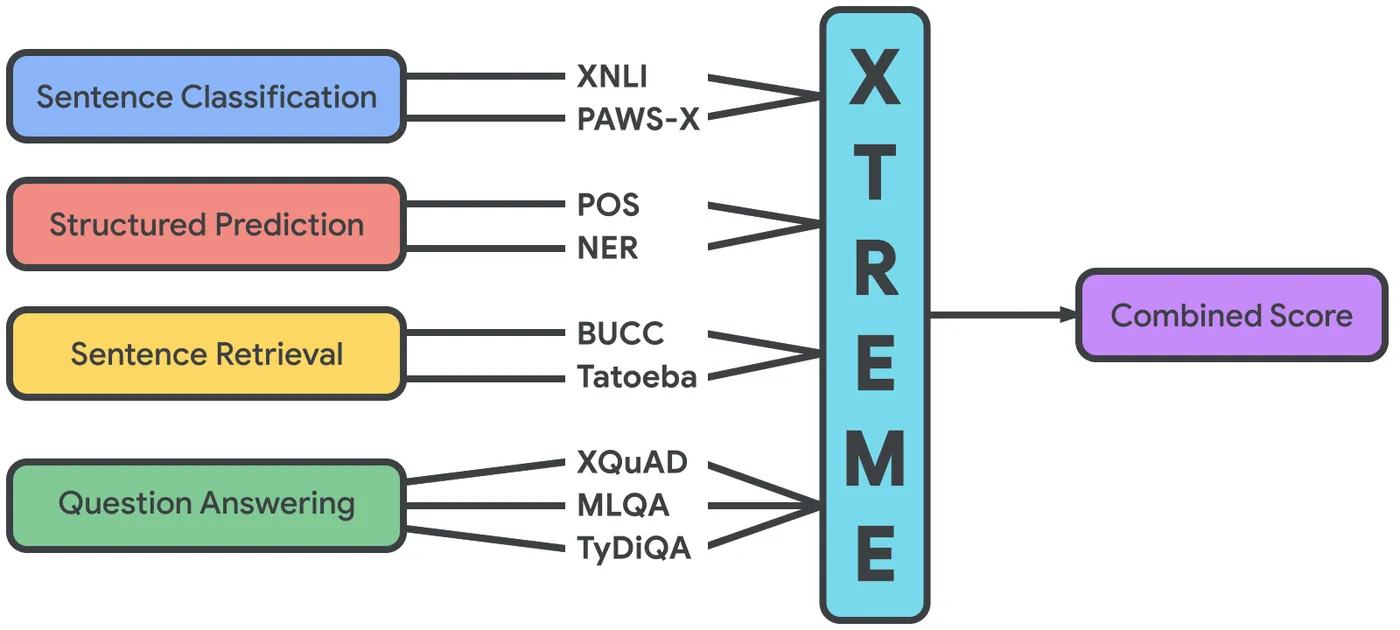
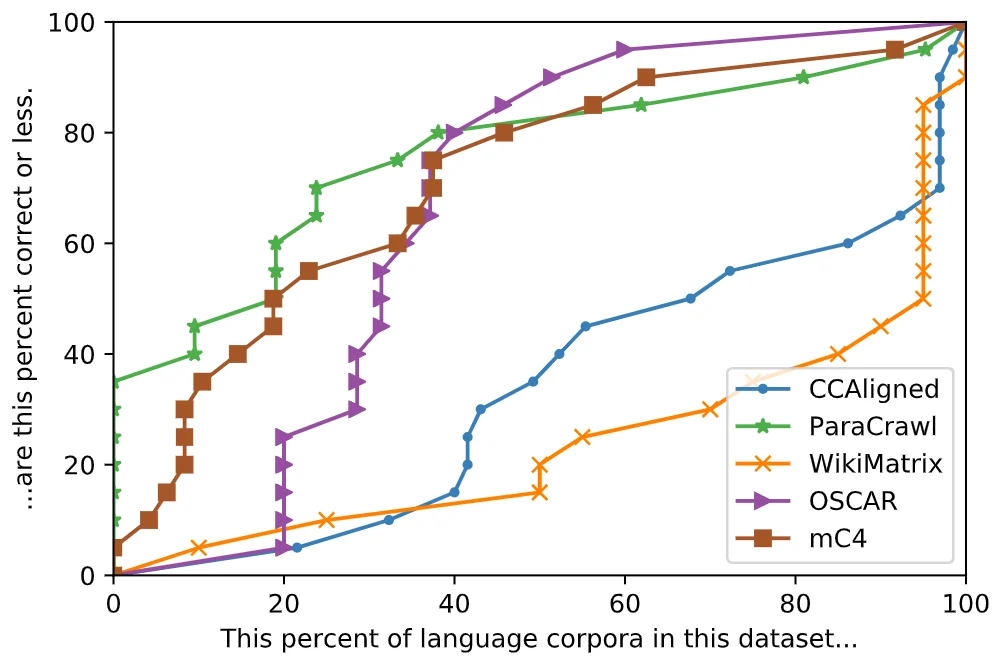
The distribution is steeply skewed. The large multilingual web corpora typically cover five to a few dozen languages well, and the published token counts drop by orders of magnitude outside the top handful. If you work in a genuinely low-resource language, expect the realistic options to be religious texts, government publications, Wikipedia and whatever you can assemble yourself — which is a different scale of project from fine-tuning in a well-served language, and worth scoping honestly before committing.
| Dataset | Modality | Size | Licence | Best for |
|---|---|---|---|---|
| FLORES+: Multilingual Translation Benchmark | Text | 2,000 sentences | CC BY-SA 4.0 | Translation models |
| English—French Parallel Translation Dataset | Text | 22,500,000 sentences | ODbL | High-performance machine translation |
| EXAMS - Multilingual school exam questions | Text | 24,000 questions | CC BY-SA 4.0 | Multilingual question answering |
| WIT Base | Multimodal | 6.5M examples | CC BY-SA 3.0 | Combine images and text |
| WMT SQM Human Evaluation | Text | 109,600 examples | Apache 2.0 | Machine translation quality |
| FineWeb2 Edu Japanese | Text | 120M texts | ODC-By | Japanese language models |
| FineFrench v1 | Text | 125M documents | ODC-By | French language models |
| VietVault: Large-Scale Vietnamese Corpus | Text | 80 GB | ODC-By | Vietnamese language models |
FLORES+: Multilingual Translation Benchmark
- Size
- Approximately 2,000 sentences per language × 230 language varieties, structured text format
- Licence
- CC-BY-SA 4.0
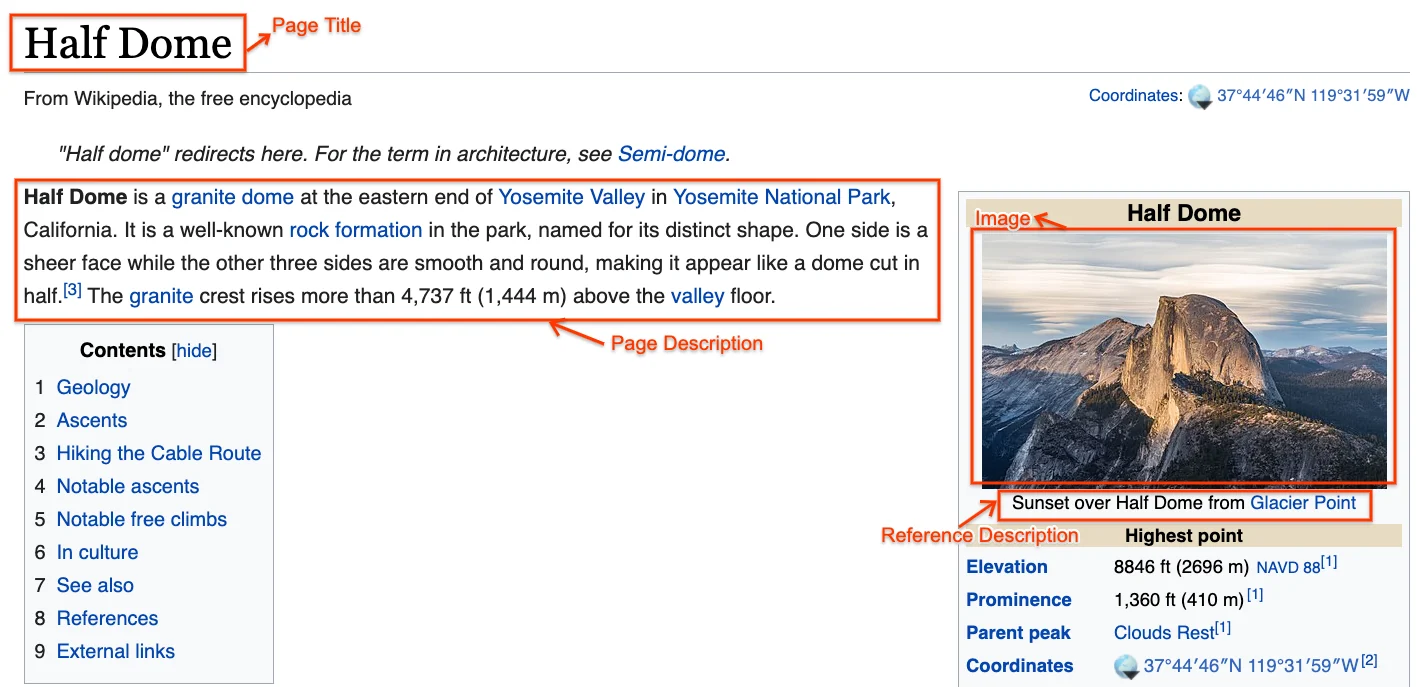
Roughly 2,000 parallel sentences per language across 230 language varieties, drawn from Wikinews, Wikivoyage and Wikijunior. One of the widest-coverage open translation benchmarks, and multi-way parallel: every language shares the same source sentences.
Evaluating translation models on low- and high-resource languages, testing multilingual systems in a controlled setting, and exploring LLM or NMT language coverage.
Source: innovatiana.com
English—French Parallel Translation Dataset
- Size
- ~22,500,000 aligned sentences, text format (TSV/CSV) two columns (English/French)
- Licence
- Open Database License (ODbL) or equivalent
About 22.5 million aligned English-French sentence pairs in two-column TSV or CSV, gathered by web collection and used as the basis for the 2015 Workshop on Statistical Machine Translation. Very large for a single language pair.
Training high-performance machine translation, fine-tuning multilingual LLMs for translation or bilingual generation, and studying corpus alignment methods.
Source: innovatiana.com
EXAMS - Multilingual school exam questions
- Size
- More than 24,000 questions in 16 languages and 24 subjects (136,082 rows across overlapping configurations)
- Licence
- CC BY-SA 4.0
More than 24,000 high school exam questions across 16 languages and 24 subjects, including mathematics, biology, history and geography (row counts in the Hugging Face release are higher because its configurations overlap), with some items supplying context and answer choices. Real exam material rather than crowd-written questions.
Training multilingual question answering, evaluating cross-language generalisation, and testing educational models in a realistic context.
Source: innovatiana.com
WIT Base
- Size
- About 6.5 million examples (6,477,255; the dataset viewer previews only the first 5.15 GB, about 108,000 rows), multilingual images and captions, Parquet format
- Licence
- CC BY-SA (upstream WIT is CC BY-SA 3.0)
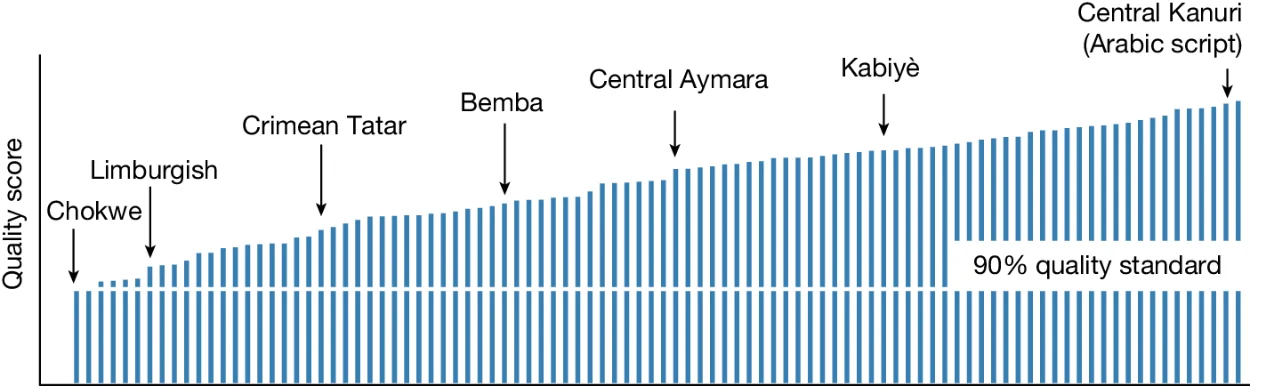
About 6.5 million Wikipedia image-and-caption examples in Parquet (the viewer previews only the first 5.15 GB, about 108,000 rows), with captions in many languages. Wikimedia provenance makes it one of the cleanest multilingual image-text sources available.
Training models that combine images and text across several languages, improving multimodal translation and image description, and testing robustness on real-world data.
Source: innovatiana.com
WMT SQM Human Evaluation
- Size
- About 109,600 human evaluation examples (109,605 rows)
- Licence
- Apache 2.0
About 109,600 human DA+SQM annotations scoring machine translation quality from the WMT 2022 task, each with source text, translation, reference, score and metadata such as language pair, domain and year.
Evaluating machine translation quality, analysing inter-annotator variability and stabilising scores, and comparing MT models across domains and languages.
Source: innovatiana.com
| language | stem | choices | answerKey |
|---|---|---|---|
| German | Der durchschnittliche Salzgehalt des Meerwassers: | A 35% · B 35‰ · C 30‰ · D 30% | B |
| French | Le taux moyen de salinité de l’eau de la mer : | A 30% · B 30‰ · C 35% · D 35‰ | D |
| Italian | La media della concentrazione del sale nell’acqua marina è: | A 35‰ · B 30% · C 35% · D 30‰ | A |
| Spanish | Contenido promedio de sal del agua de mar. | A 30‰ · B 30% · C 35‰ · D 35% | C |
| Croatian | Prosječni salinitet morske vode: | A 30% · B 30‰ · C 35% · D 35‰ | D |
| Hungarian | A tengervíz átlagos sótartalma: | A 30‰ · B 35‰ · C 30% · D 35% | B |
FineWeb2 Edu Japanese
- Size
- Approximately 120 million texts (~89.3 billion tokens), text format, subsets in Parquet format
- Licence
- Open Data Commons Attribution License (ODC-by) v1.0
Roughly 120 million Japanese web texts totalling about 89.3 billion tokens, with subsets in Parquet, filtered for educational value so that most web noise is removed. The Japanese counterpart to FineWeb-Edu.
Training and evaluating Japanese language models for education and comprehension, improving LLMs for learning assistants, and studying large-scale web text filtering.
Source: innovatiana.com
FineFrench v1
- Size
- About 125 million documents (some 66 million rated high quality), JSONL/parquet format, 283 GB
- Licence
- ODC-by 1.0
About 125 million French-language web documents from FineWeb-2 in JSONL and Parquet (283 GB), of which a CamemBERT classifier trained on GPT-4o labels rates some 66 million as high quality and flags the rest. A FineWeb-style corpus for French.
Training French language models, experimenting with automated web text cleaning, and serving as a base for semantic analysis, summarisation or content classification.
Source: innovatiana.com
VietVault: Large-Scale Vietnamese Corpus
- Size
- 80GB of text, raw Markdown format (UTF-8), line per document
- Licence
- ODC-by
80 GB of Vietnamese text in raw UTF-8 Markdown, one document per line, built from Common Crawl between 2013 and 2023 then cleaned, deduplicated and filtered for toxic content. Unannotated, intended for pre-training.
Pre-training Vietnamese language models such as BERT, RoBERTa or GPT, fine-tuning on classification, NER or summarisation, and modelling modern Vietnamese.
Source: innovatiana.com
How this list was put together
Drawn from the datasets in Dataset Finder filed under this topic, then checked by hand against what this page covers. A tag is a filing decision, not a description, so records that carried the tag without being about the topic were removed, and relevant records filed elsewhere were added. The order puts the closest fit first.
Sizes and licences come from each dataset's own documentation, vague wording included. Where we found a re-upload or catalogue card stating a licence that the original release contradicts — a CC0 tag on Flickr photographs, MIT on data whose terms require a signed agreement — the entry gives the original terms and says so. The comparison table abbreviates licences; hover a cell for the full wording.