NER datasets are abundant and mutually incompatible, because every one defines its own entity types and tagging convention.
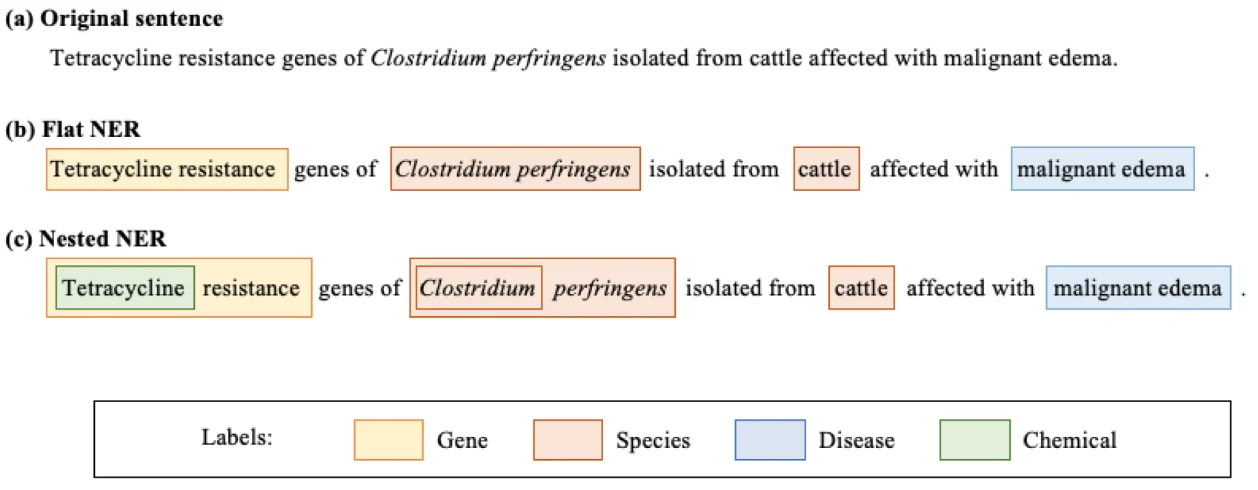
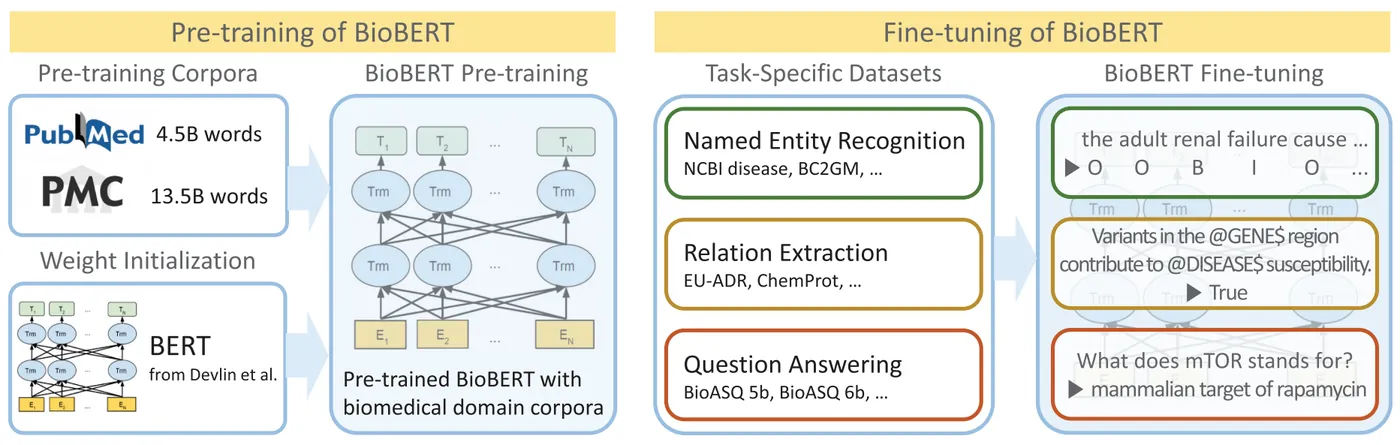
Two sources of incompatibility. The entity inventory — one dataset has person, organisation, location and miscellaneous; another has forty biomedical types; a third has legal-specific categories. And the tagging scheme, where several conventions exist for marking the beginning and continuation of multi-token entities. Both must be aligned before datasets can be combined, and the alignment loses information wherever the inventories do not nest cleanly.
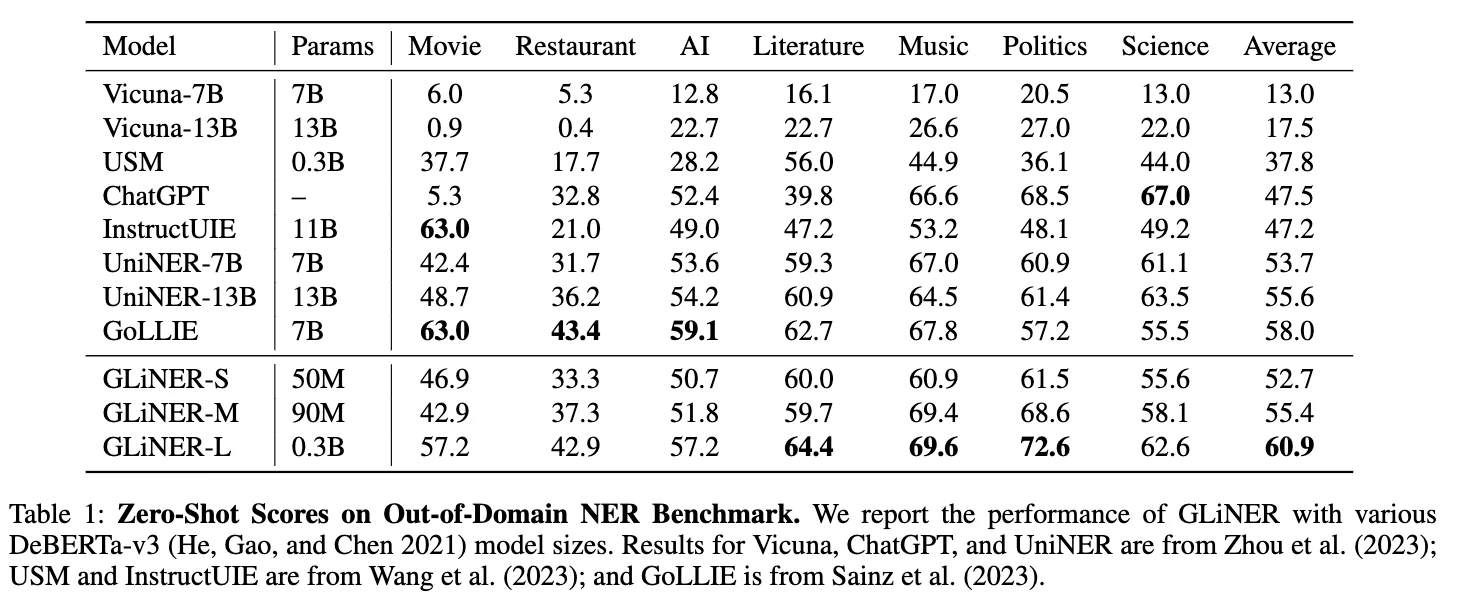
Domain matters more here than in most classification tasks because entity boundaries are domain-specific. A general-purpose model will not reliably find gene names, drug dosages or statutory references, and a biomedical model will not help with contract parties. Pick for domain first and scale second.
This list is deliberately short. Entity recognition data is plentiful in the sense that many corpora contain names, and scarce in the sense that matters: text annotated span by span, to a written guideline, with a stated tag scheme. Corpora that merely mention entities were removed. Before you merge any two of the sets below, compare their entity inventories line by line — one corpus's organisation is another's location, and the merged model learns the contradiction.
| Dataset | Modality | Size | Licence | Best for |
|---|---|---|---|---|
| CoNLL-2003 | Text | 301,418 tokens | Research only | Named entity recognition |
| RONEC | Text | 12,330 sentences | MIT | Named entity recognition models |
| Text Anonymization Benchmark | Text | 1,268 documents | MIT | Automatic anonymisation |
| Text Extraction for OCR | Multimodal | 1,560 images | CC0 | Invoice-specific entity extraction |
CoNLL-2003
- Size
- 301,418 English tokens (train, dev and test), IOB1 tags in CoNLL column format
- Licence
- Annotations free; the Reuters text must be obtained from NIST, which supplies it for research purposes only
Several hundred thousand tokens of journalistic text annotated with IOB1 tags (re-releases often convert them to BIO) for people, places, organisations and miscellaneous entities, introduced with the CoNLL-2003 shared task. Still the default named-entity recognition benchmark.
Training named entity recognition, comparative evaluation of NLP architectures, extracting information from documents, and improving search and monitoring systems.
Source: innovatiana.com
RONEC
- Size
- Approximately 12,330 sentences, 0.5 million tokens, JSON/Parquet format, 2.94 MB
- Licence
- MIT
About 12,330 annotated sentences and half a million tokens in JSON and Parquet, 2.94 MB, with 15 entity classes and over 80,000 distinct entities. RONEC is the Romanian Named Entity Corpus, although its catalogue page describes it as French.
Training named entity recognition models, improving information extraction from text, and testing NER accuracy on manually annotated data.
Source: innovatiana.com
Text Anonymization Benchmark
- Size
- 1,268 documents in English in annotated JSON format
- Licence
- MIT
1,268 English judgments from the European Court of Human Rights in annotated JSON, marked up with named entities, their categories, their confidential status and coreference links between mentions. Purpose-built for anonymisation.
Training automatic anonymisation of legal or sensitive texts, studying bias around personal information in documents, and testing NER detection and masking systems.
Source: innovatiana.com
{
  "entity_type": "ORG",
  "entity_mention_id": "001-83927_a1_em2",
  "start_offset": 76,
  "end_offset": 94,
  "span_text": "Republic of Turkey",
  "edit_type": "insert",
  "confidential_status": "NOT_CONFIDENTIAL",
  "identifier_type": "NO_MASK",
  "entity_id": "001-83927_a1_e2"
}
{
  "entity_type": "DATETIME",
  "entity_mention_id": "001-83927_a1_em5",
  "start_offset": 292,
  "end_offset": 307,
  "span_text": "15 October 2004",
  "edit_type": "check",
  "identifier_type": "QUASI",
  "entity_id": "001-83927_a1_e5",
  "confidential_status": "NOT_CONFIDENTIAL"
}
Text Extraction for OCR
- Size
- About 1,560 invoice images (JPG/PNG) paired with XML entity annotations, including extracted tabular data
- Licence
- CC0: Public Domain
About 1,560 pairs of invoice images in JPG or PNG with XML files holding extracted entities such as invoice number, date, business name, telephone and address, plus extracted tabular data. A ready-made document-NER set.
Developing invoice-specific entity extraction, improving recognition of tabular data in complex images, and building OCR robust to typographic and quality errors.
Source: innovatiana.com
How this list was put together
Found by searching Dataset Finder for datasets whose documentation describes the task, then checked by hand. A keyword match is not a fit — the first pass picked up a coral survey for the depth-estimation list because it was recorded below fifty metres — so every entry was read against what this page covers, and the ones that matched a word without matching the task were removed.
Sizes and licences come from each dataset's own documentation, vague wording included. Where we found a re-upload or catalogue card stating a licence that the original release contradicts — a CC0 tag on Flickr photographs, MIT on data whose terms require a signed agreement — the entry gives the original terms and says so. The comparison table abbreviates licences; hover a cell for the full wording.