Segmentation labels every pixel, which makes the annotation expensive and its quality far more variable than in detection data.
Semantic segmentation assigns a class to every pixel without distinguishing individual objects — all cars are 'car'. That is the right task for road scenes, land cover, and medical regions, and the wrong one if you need to count things, which is instance segmentation.
Mask quality is the property to inspect. Masks are expensive to draw precisely, so datasets vary enormously in boundary accuracy, and many large sets contain polygon approximations or machine-generated masks rather than careful human tracing. Look at a few masks at full resolution before you commit — boundary sloppiness that is invisible at thumbnail size sets a hard ceiling on what your model can learn.
| Dataset | Modality | Size | Licence | Best for |
|---|---|---|---|---|
| Cityscapes Dataset | Image | 5,000 images | Research only | Urban segmentation models |
| Pascal VOC | Image | 20,000 images | Research only | Object detection and classification |
| ScanNet | Image | 1,513 scans | Gated access | 3D semantic segmentation |
| Topview Lane | Image | 7,467 images | MIT | Road lane segmentation |
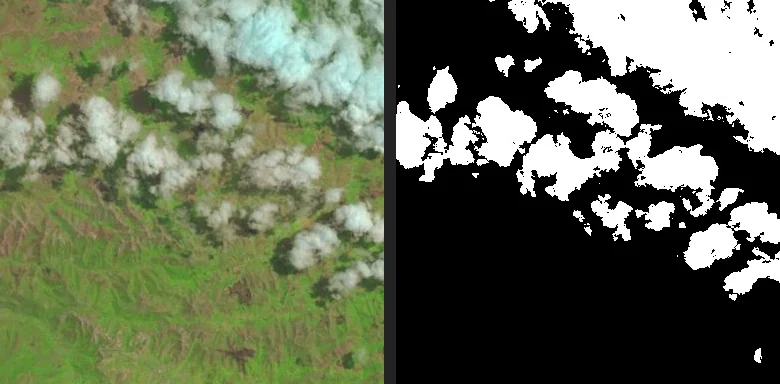
| 38-Cloud: Cloud Segmentation on Satellite Images | Image | 17,601 patches | Unclear — see below | Semantic segmentation for cloud detection |
| Chest X-ray Masks and Labels | Medical | 2,403 files | CC0 | Lung segmentation models |
| HPA Mask | Medical | 43,600 masks | CC0 | Biomedical semantic segmentation models |
| Pothole Image Segmentation Dataset | Image | 780 images | Apache 2.0 | Pothole segmentation models |
| Open Images Dataset | Image | 9M images | Mixed — see below | Object detection and segmentation |
Cityscapes Dataset
- Size
- Approximately 5,000 high-resolution images in PNG format, annotations in JSON
- Licence
- Usable for academic research purposes under a specific license (Cityscapes Research License)
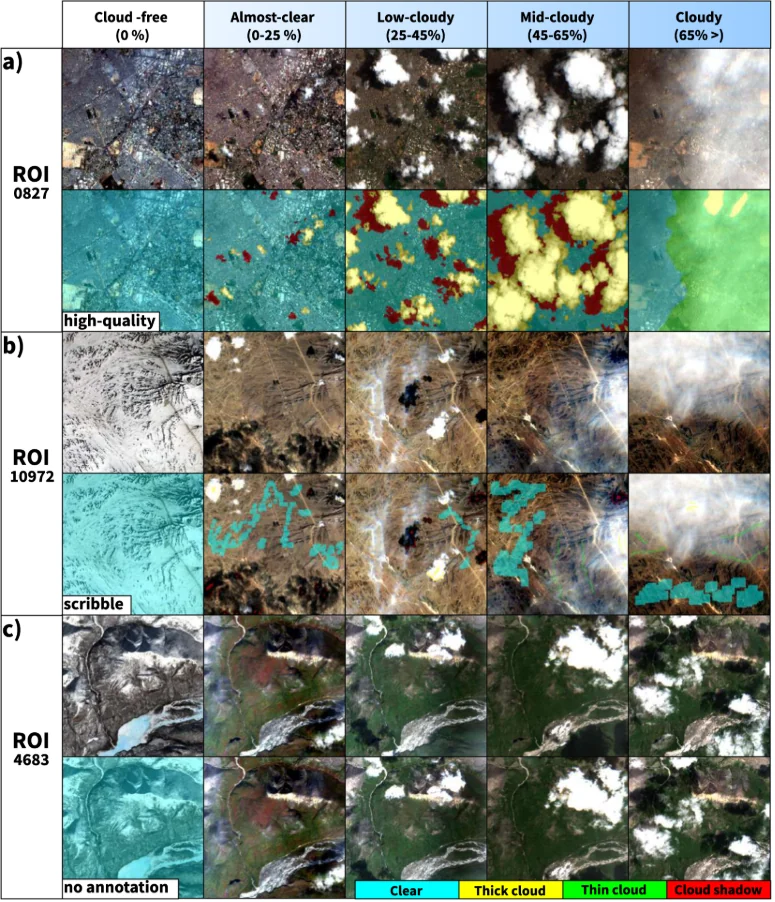
Around 5,000 high-resolution PNG images of annotated urban street scenes with JSON annotations, the reference set for semantic segmentation in driving contexts. Use is governed by the Cityscapes Research License and restricted to non-commercial use (academic research, teaching, publications, personal experimentation).
Training urban segmentation models, street scene analysis for autonomous vehicle perception, and recognising objects and behaviours in traffic.
Source: innovatiana.com
Pascal VOC
- Size
- Approximately 20,000 images in JPEG format, XML annotations, 20 object categories
- Licence
- Free for use in academic and non-commercial research
About 20,000 JPEG images with XML annotations across 20 object categories, of which only a subset has segmentation masks: VOC2012's 11,530 train/val images carry 6,929 object segmentations. Small by modern standards but still the format many detection toolchains expect, and the baseline against which older detectors are quoted.
Training and evaluating object detection and classification, semantic segmentation, establishing benchmarks for new models, and transfer learning.
Source: innovatiana.com
ScanNet
- Size
- 1,513 annotated RGB-D scans, 2D/3D formats (images, voxels, meshes, depth maps)
- Licence
- ScanNet Terms of Use for the data (signed agreement required); code under MIT
1,513 annotated indoor RGB-D scans covering 20 object classes, delivered across 2D and 3D formats including images, voxels, meshes and depth maps. The reference dataset for indoor 3D semantic segmentation. Only the code is MIT: the data is released under the ScanNet Terms of Use, which you sign to request access.
3D semantic segmentation, interior scene reconstruction, object detection and tracking in enclosed spaces, and robotic perception and indoor navigation.
Source: innovatiana.com
Topview Lane
- Size
- 7,467 annotated images, Parquet format (254 MB)
- Licence
- MIT
7,467 annotated road images captured from above and packaged as Parquet at 254 MB, for training models to detect and segment lane markings and road structure from a bird's-eye perspective rather than a dashcam view.
Road lane segmentation, developing driving assistance systems, and analysing road network structure from above for mapping.
Source: innovatiana.com
38-Cloud: Cloud Segmentation on Satellite Images
- Size
- 17,601 patches of 384×384 (8,400 train, 9,201 test), each in four bands (R, G, B, NIR), with cloud masks
- Licence
- Apache 2.0 licence file in the repository; no separate statement about the data
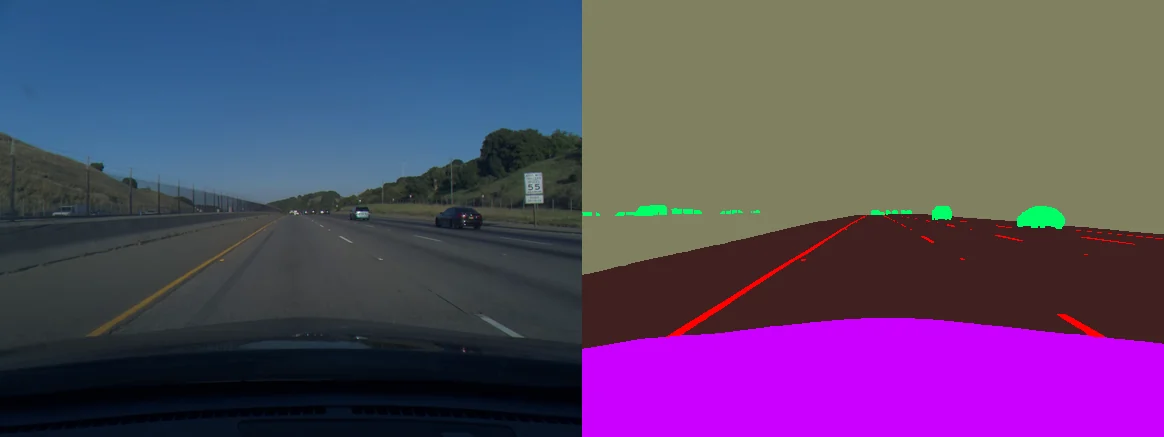
17,601 patches of 384x384 pixels cut from 38 Landsat 8 scenes (8,400 for training, 9,201 for testing), each stored as red, green, blue and near-infrared bands, with pixel-level cloud masks for the training patches. The repository carries an Apache 2.0 licence file but says nothing separately about the data.
Training semantic segmentation for cloud detection, estimating cloud cover for climate or agriculture, and improving multispectral processing.
Source: innovatiana.com
Chest X-ray Masks and Labels
- Size
- 2,403 files: chest X-rays and lung masks in PNG, with TB labels
- Licence
- CC0: Public Domain
2,403 files pairing chest radiographs in PNG, from the Montgomery County and Shenzhen tuberculosis collections, with lung segmentation masks in PNG and TB labels; some images have no mask. Because the images come from different clinical sources, it doubles as a domain-adaptation testbed as well as a segmentation set.
Training lung segmentation models, building tuberculosis or lung abnormality classifiers, and testing robustness across clinical sources.
Source: innovatiana.com
HPA Mask
- Size
- 43,600 PNG masks (cell segmentations)
- Licence
- CC0: Public Domain
43,600 automatically generated cell segmentation masks in PNG, derived from Human Protein Atlas microscopy images. The masks are intended to complete the original HPA imagery rather than stand alone, and are released into the public domain.
Training biomedical semantic segmentation models, completing HPA images for cell classification, and AI-assisted cell biology research.
Source: innovatiana.com
Pothole Image Segmentation Dataset
- Size
- 780 annotated images in YOLOv8 format, 640x640 px, with sets train (720) and validation (60)
- Licence
- Apache 2.0
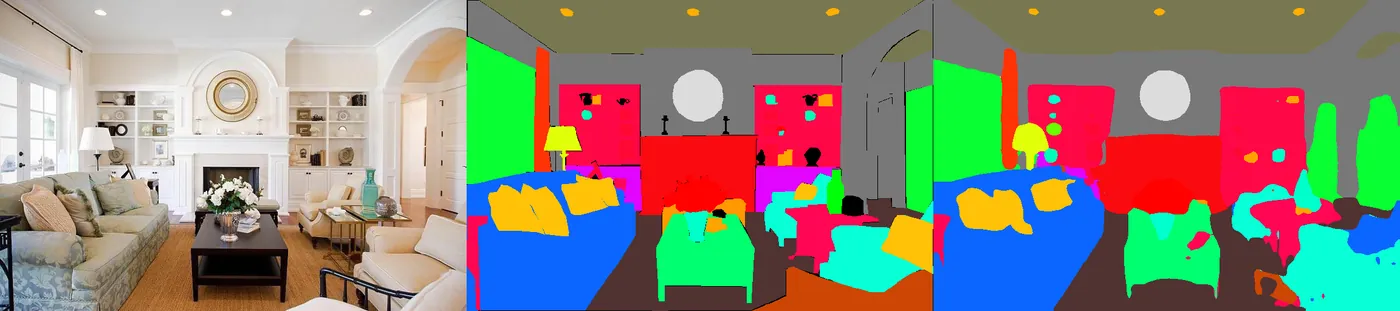
780 augmented road images resized to 640x640 and annotated in YOLOv8 segmentation format, split 720 train and 60 validation. Tiny but segmentation-ready, with a permissive Apache licence for commercial use.
Training pothole segmentation models, developing automatic road monitoring and maintenance, and improving safety through damage detection.
Source: innovatiana.com
Open Images Dataset
- Size
- Over 9 million images in JPEG format, detailed annotations in CSV
- Licence
- Annotations CC BY 4.0 (Google); images listed as CC BY 2.0, each image's licence to be verified by the user
Over nine million JPEG images with detailed CSV annotations covering objects, segmentation masks and relationships between objects. Its annotations are CC BY 4.0 and its images are listed as CC BY 2.0, so commercial use is possible with attribution, though Google makes no warranty about any single image's licence.
Training object detection and segmentation, analysing relationships between objects, improving visual search, and building robust versatile models.
Source: innovatiana.com
How this list was put together
Found by searching Dataset Finder for datasets whose documentation describes the task, then checked by hand. A keyword match is not a fit — the first pass picked up a coral survey for the depth-estimation list because it was recorded below fifty metres — so every entry was read against what this page covers, and the ones that matched a word without matching the task were removed.
Sizes and licences come from each dataset's own documentation, vague wording included. Where we found a re-upload or catalogue card stating a licence that the original release contradicts — a CC0 tag on Flickr photographs, MIT on data whose terms require a signed agreement — the entry gives the original terms and says so. The comparison table abbreviates licences; hover a cell for the full wording.